

Medical Vision Encoder - 2048-D
Madrimed 1.2 Vision Embed
Model Overview
This vision encoder is an isolated visual representation tower for dense feature extraction from multi-modality radiological scans other medical images. It projects dynamic-resolution medical imagery into an L2-normalized 2048-dimensional embedding space, optimized for cross-modal alignment and topological Graph Retrieval-Augmented Generation.
Key Architectural Specifications
- Model Type: Vision Transformer (ViT) with patch-merging projection
- Feature Dimension: 2048 (matches transformer language model input dimensions)
- Spatial Patch Merger: $2 \times 2$ patch compression via linear projection
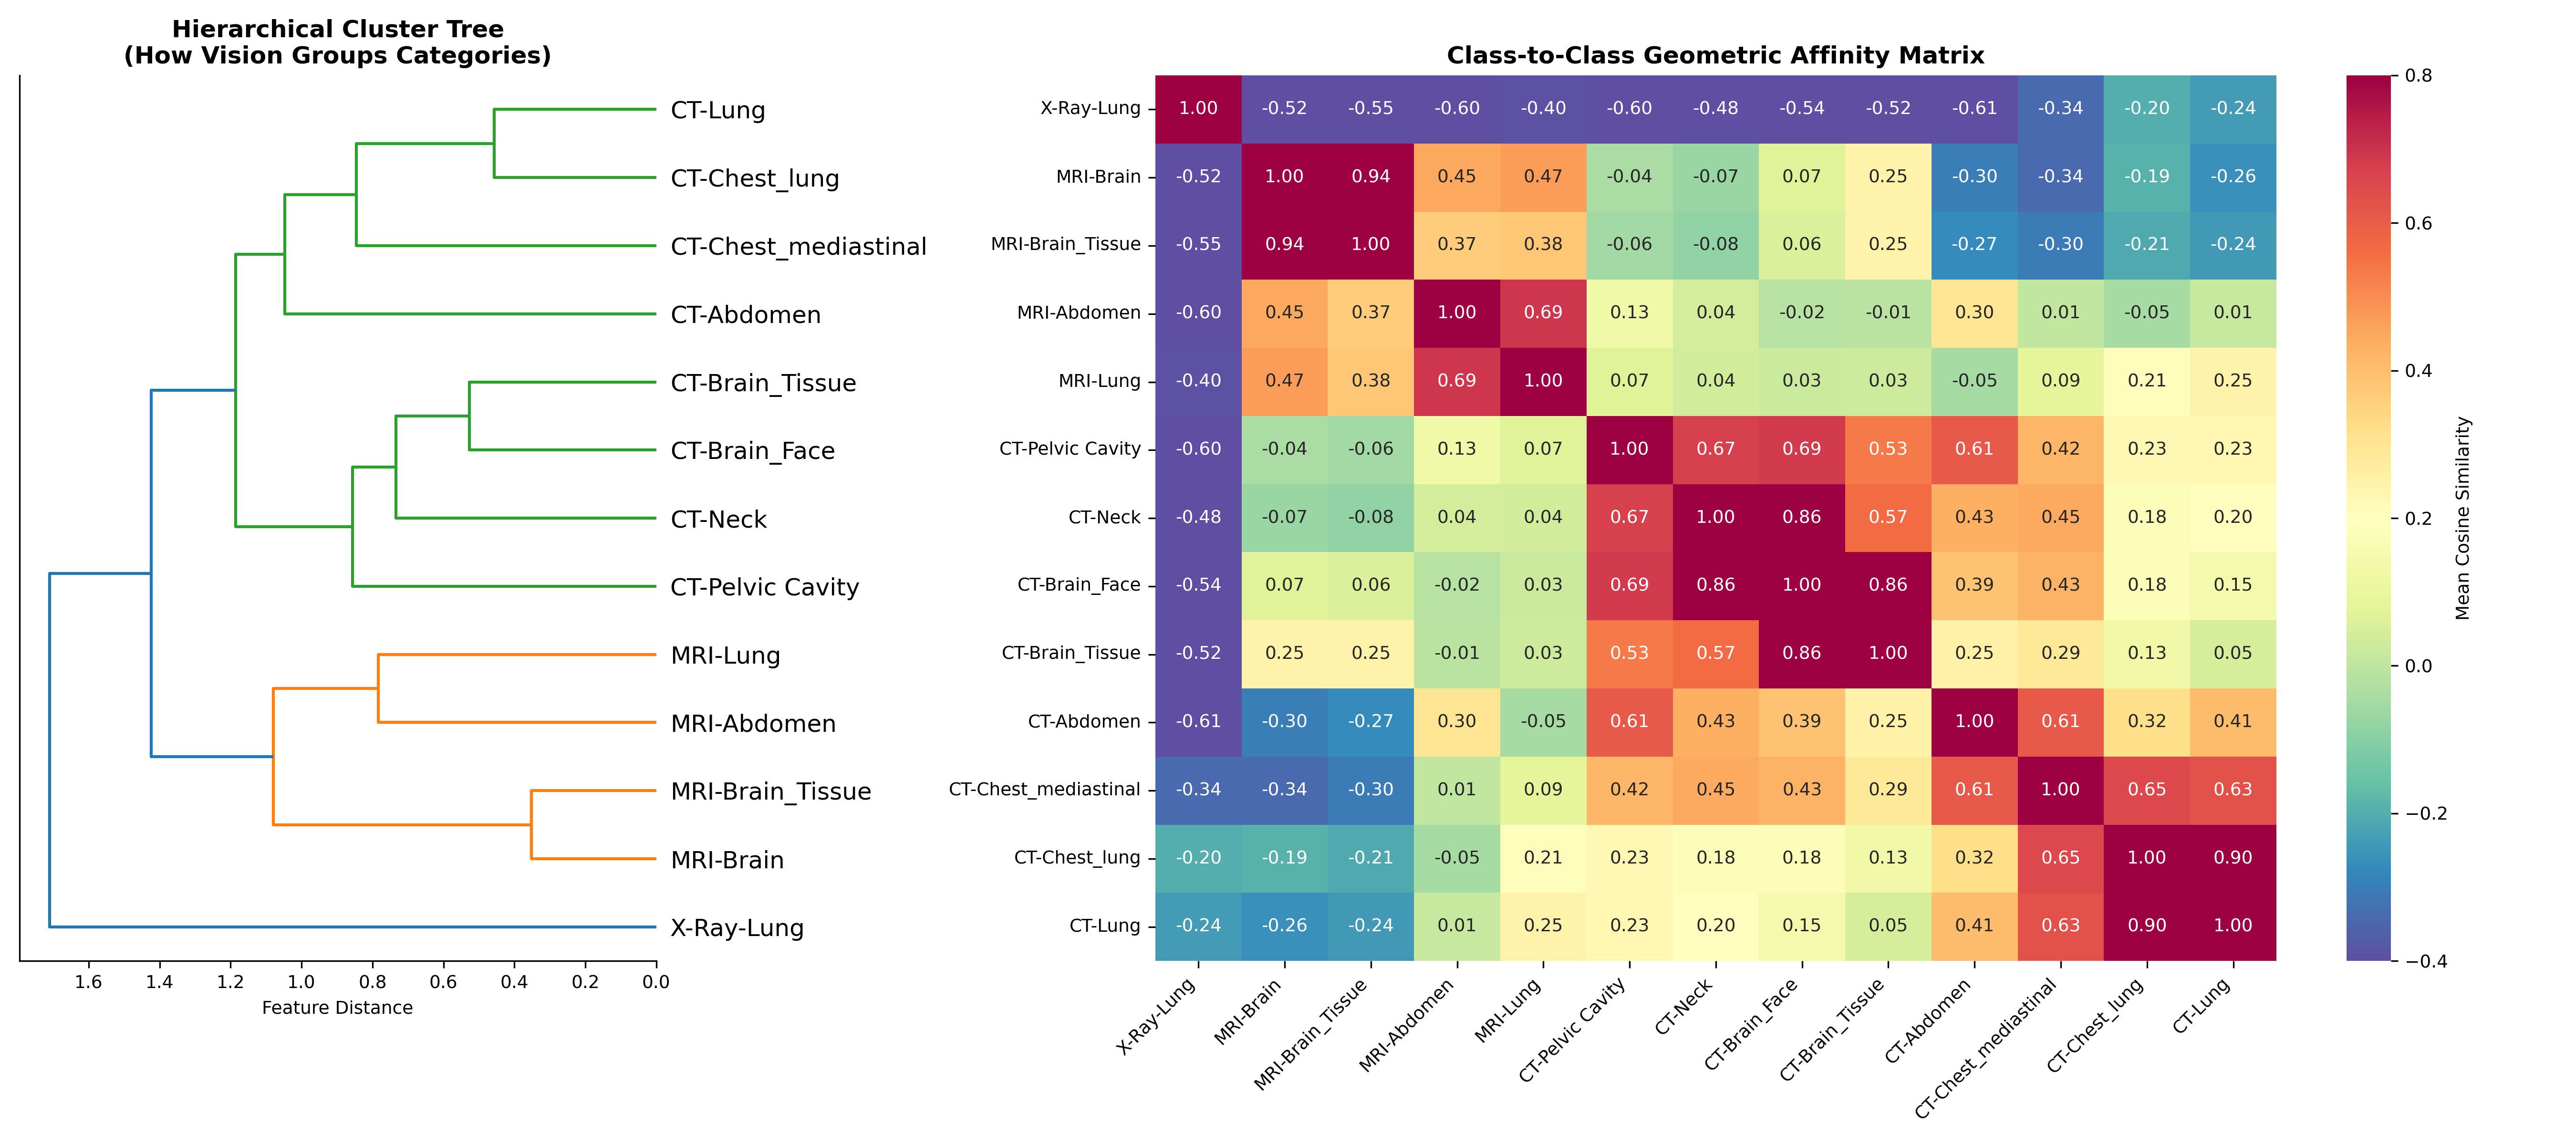
- Primary Feature Structure: Modality-dominant feature geometry (groups scans primarily by imaging physics and tissue contrast)
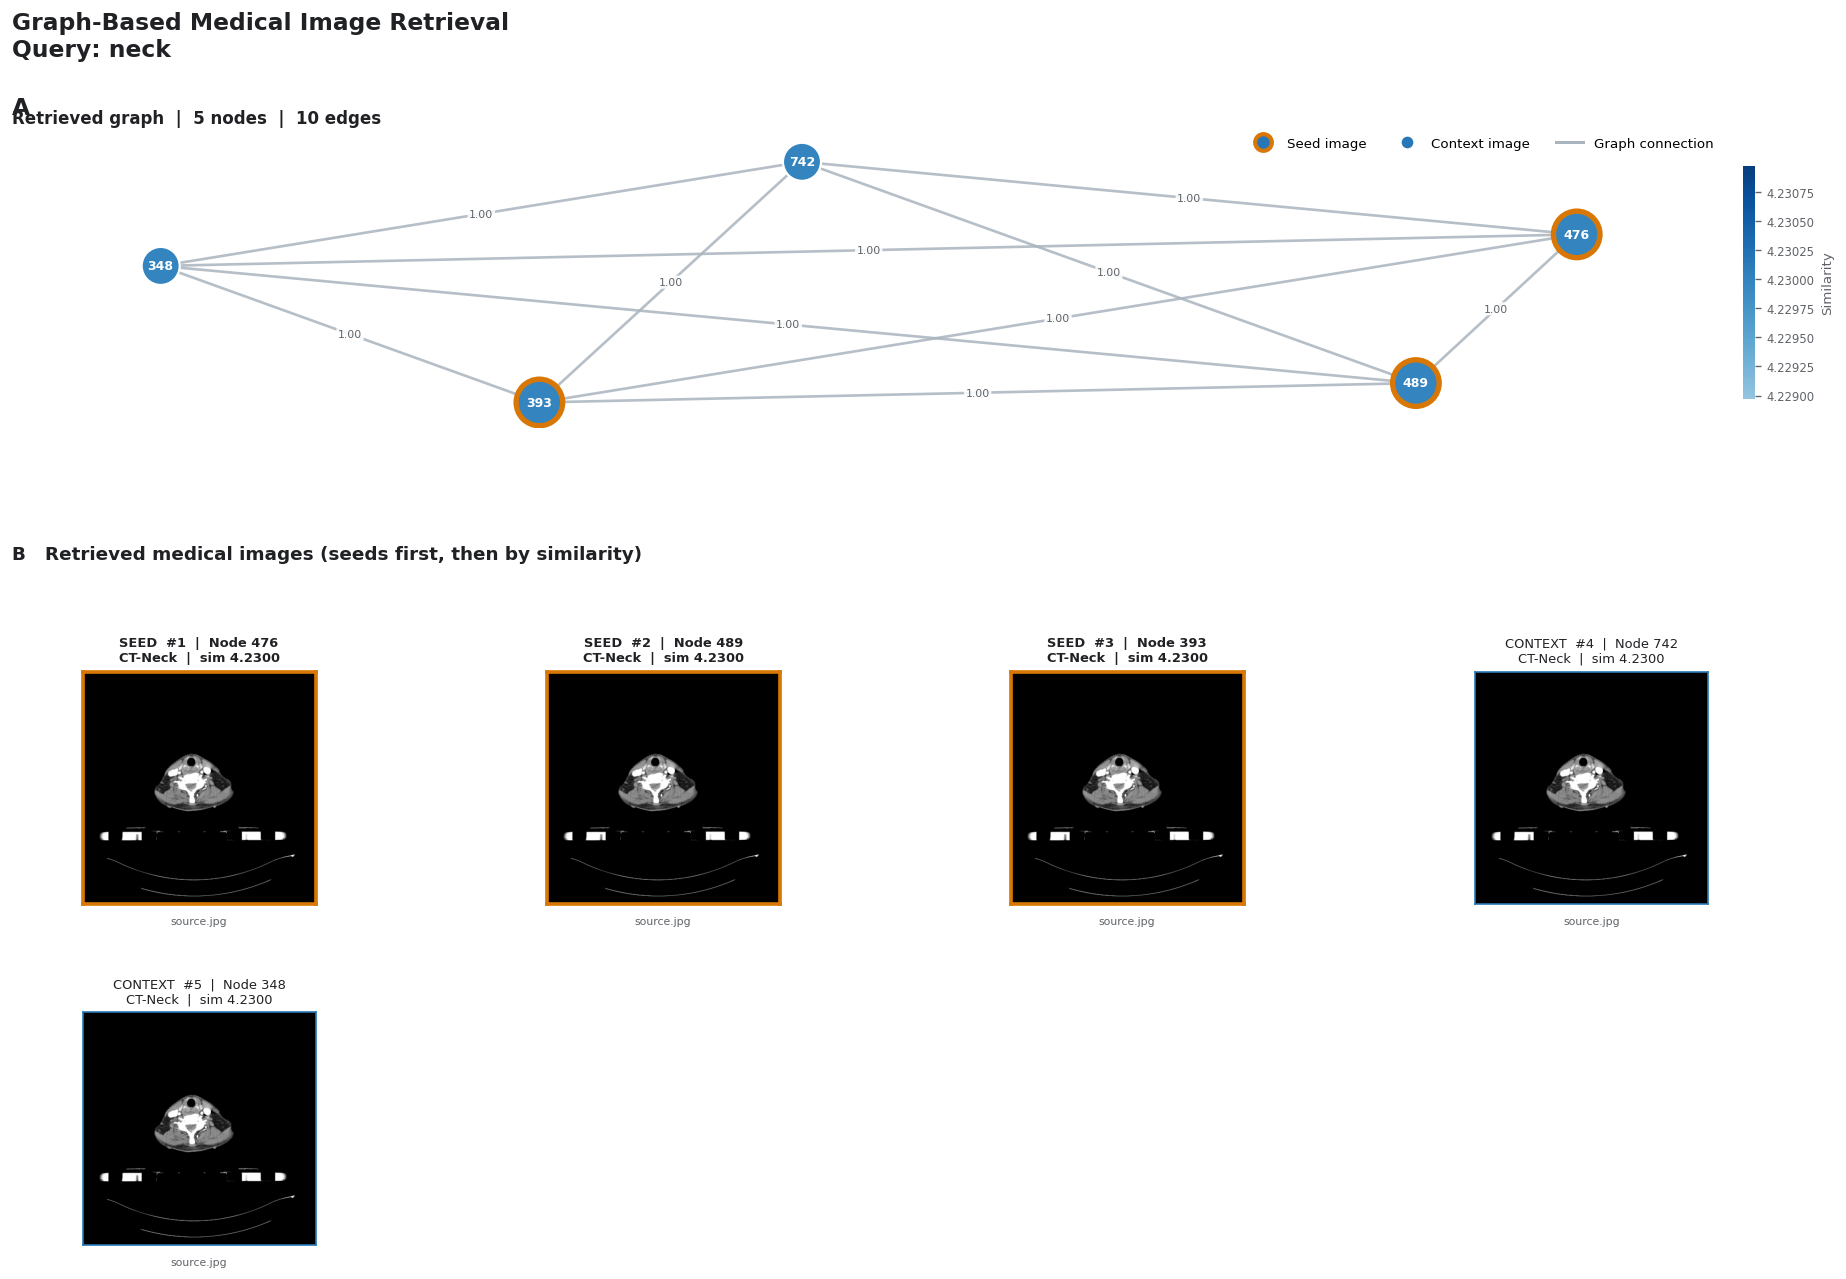
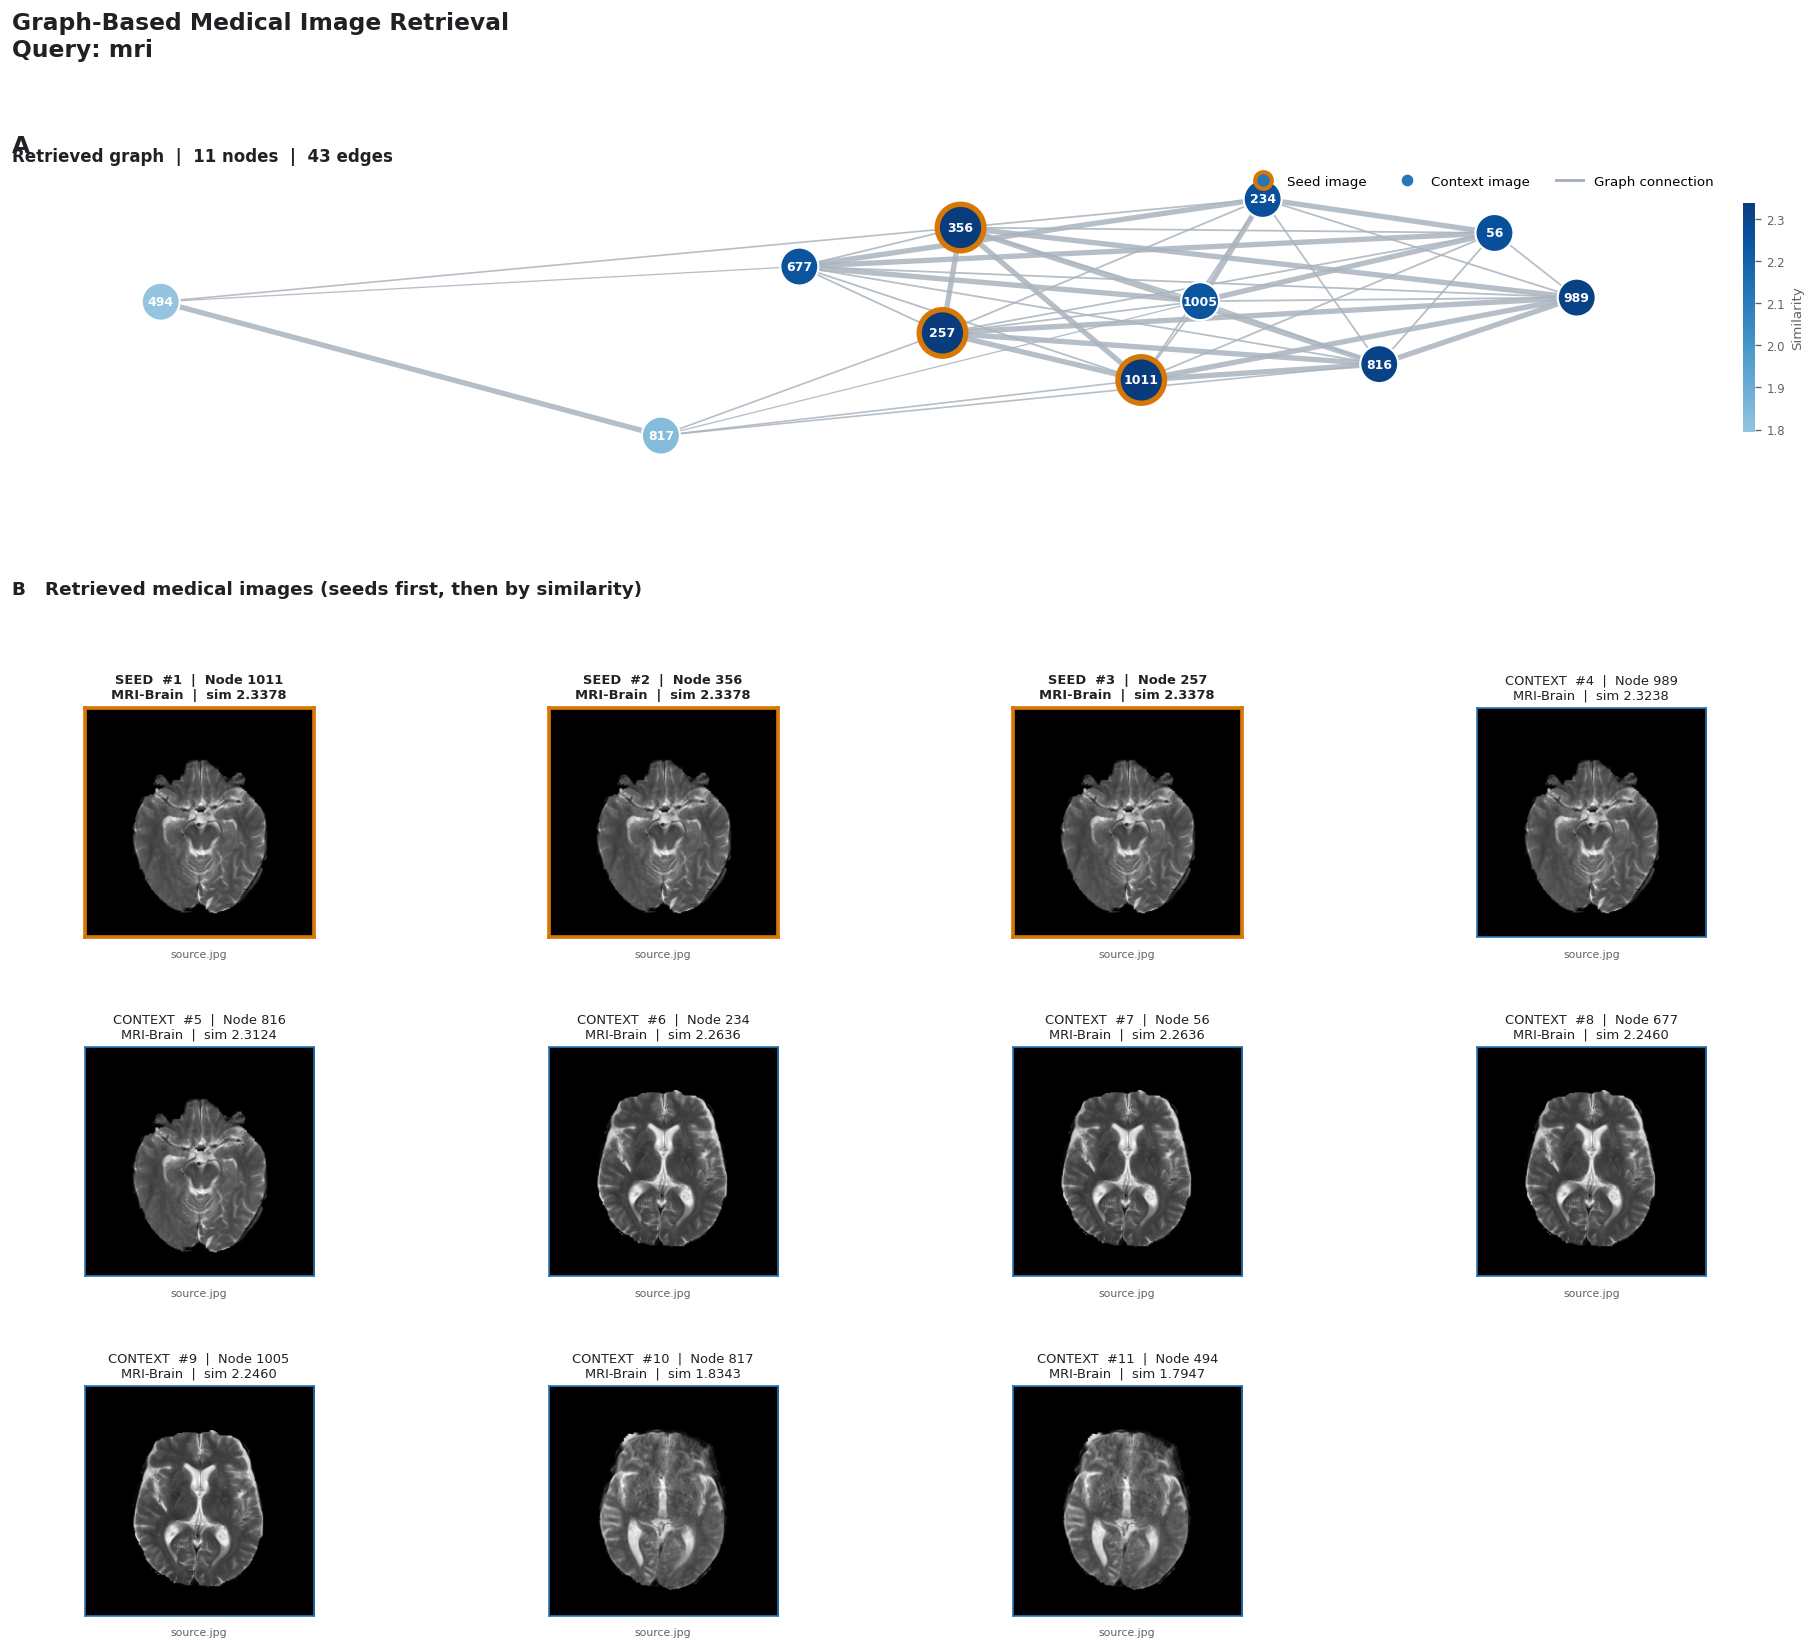
Visual Retrieval Using Text Queries with madrisight/madrimed1.2-text-embed
 |  |
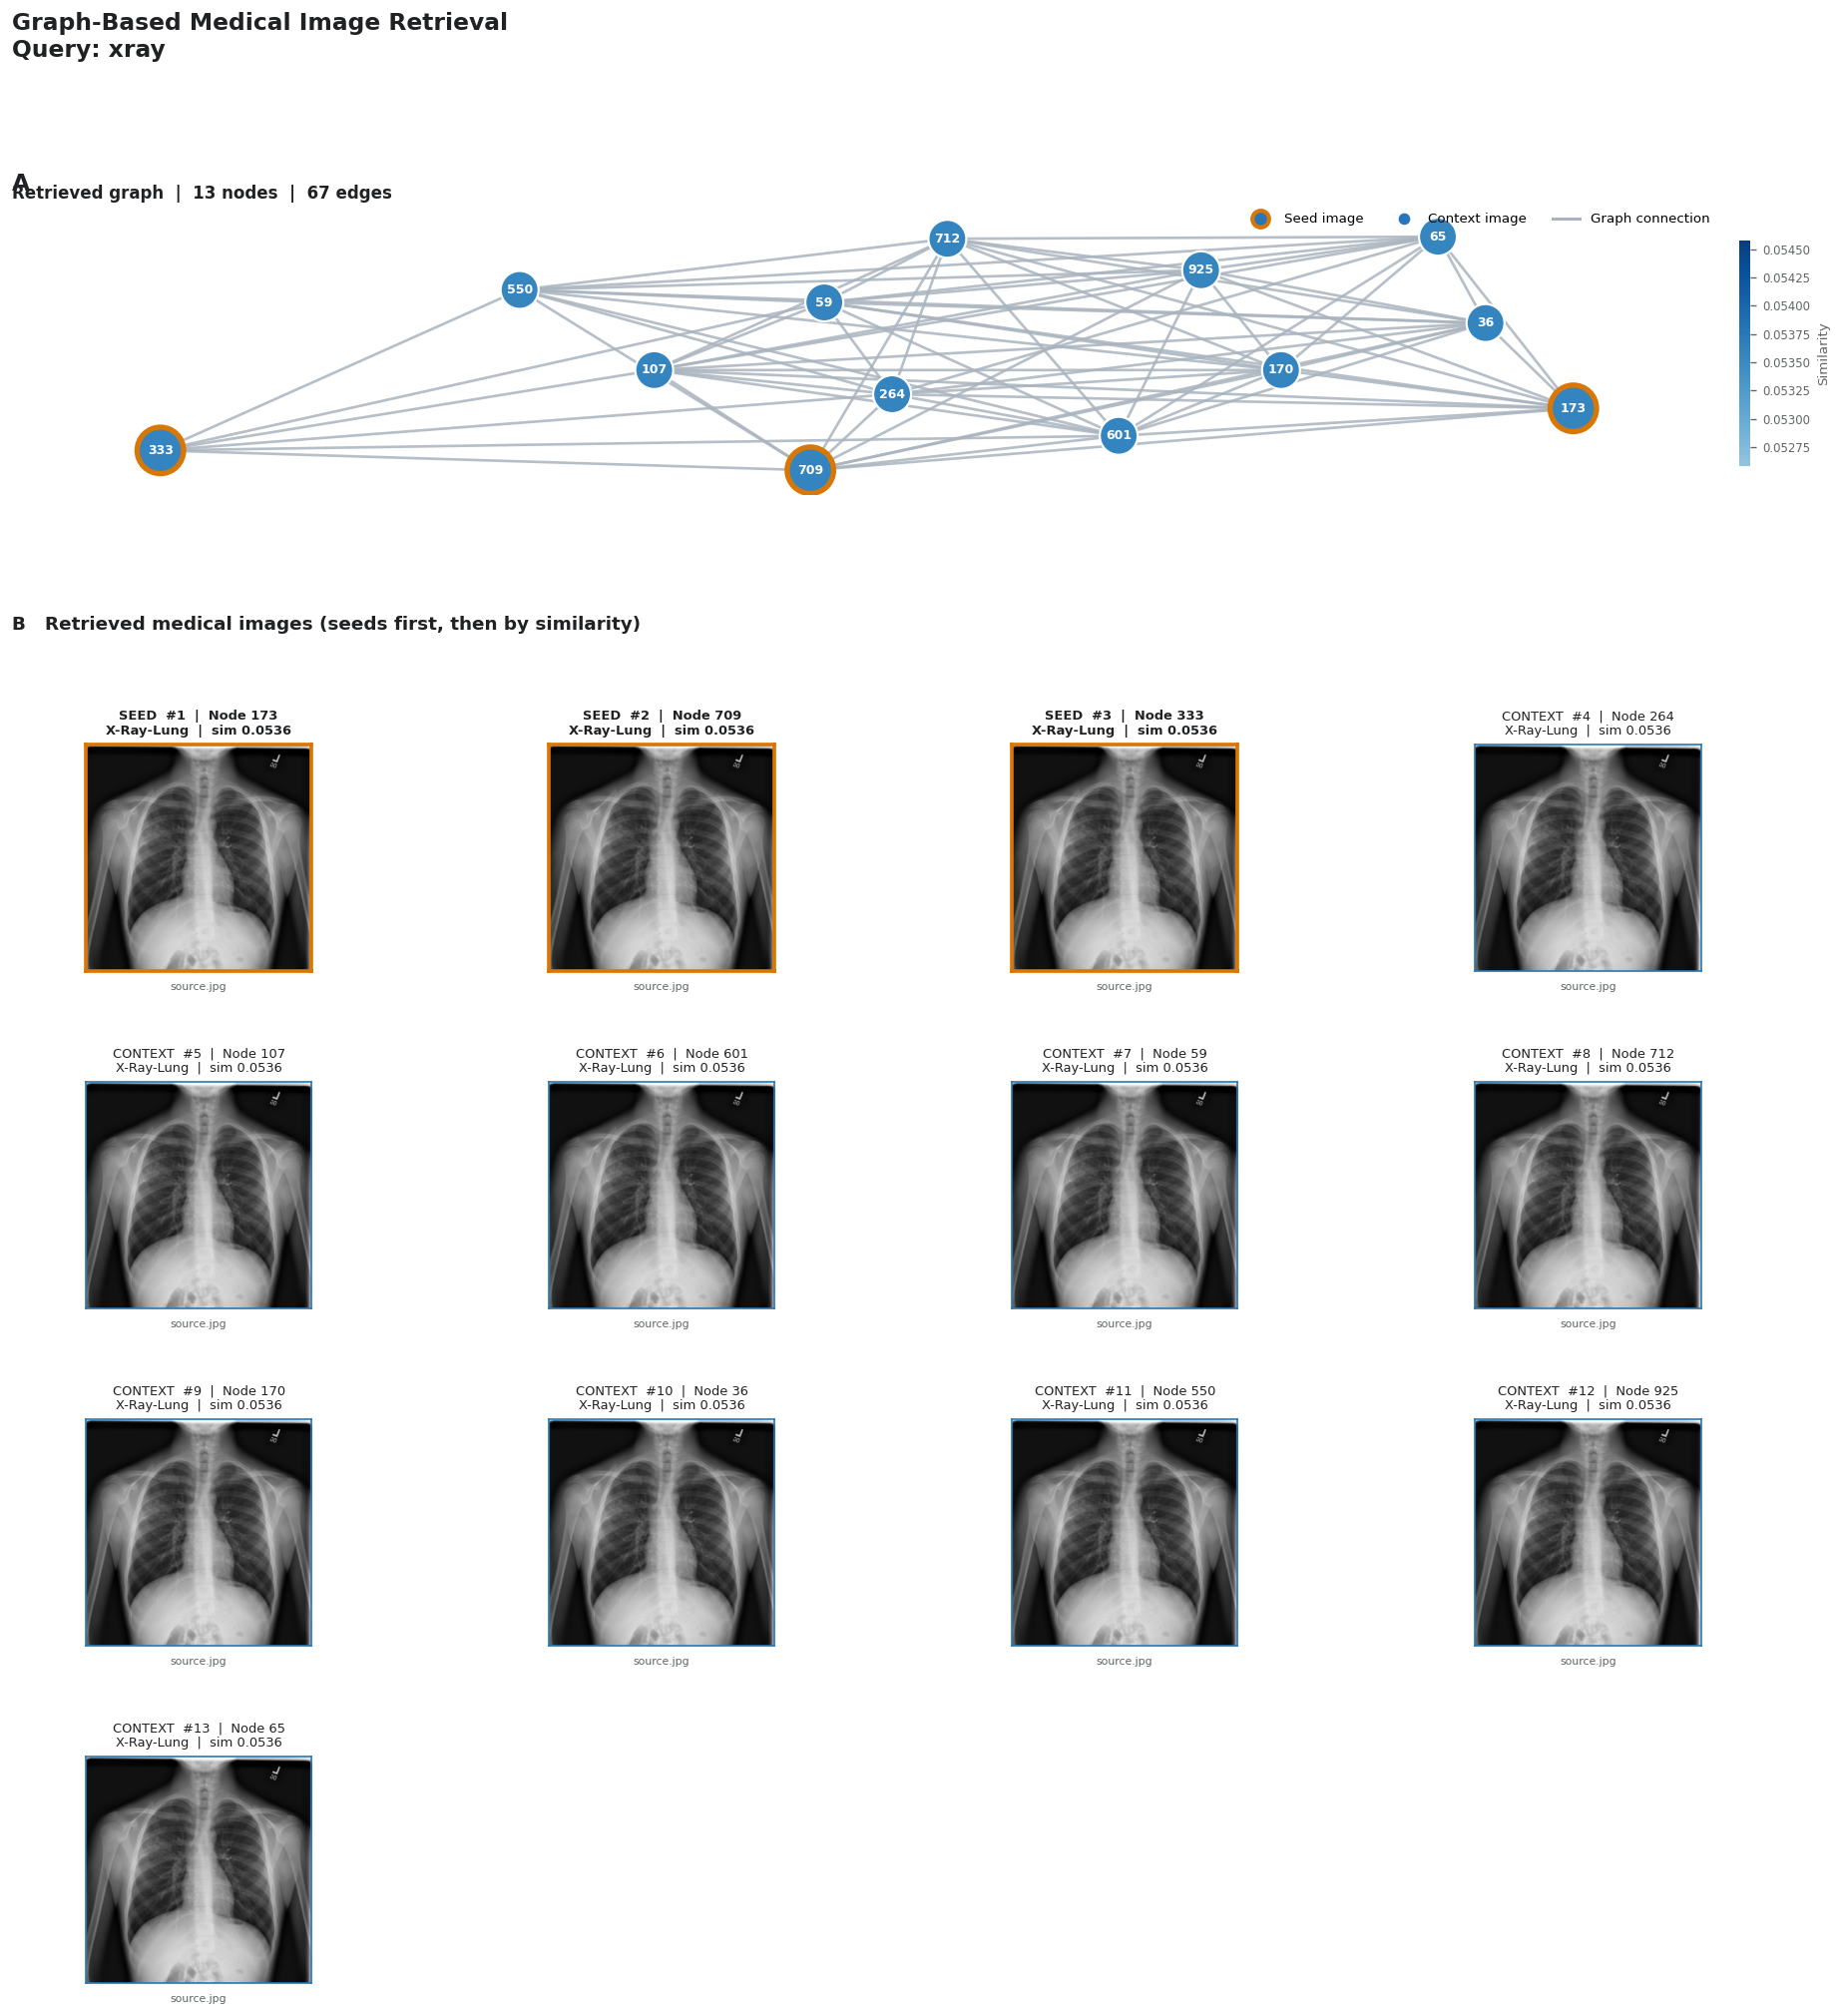 | 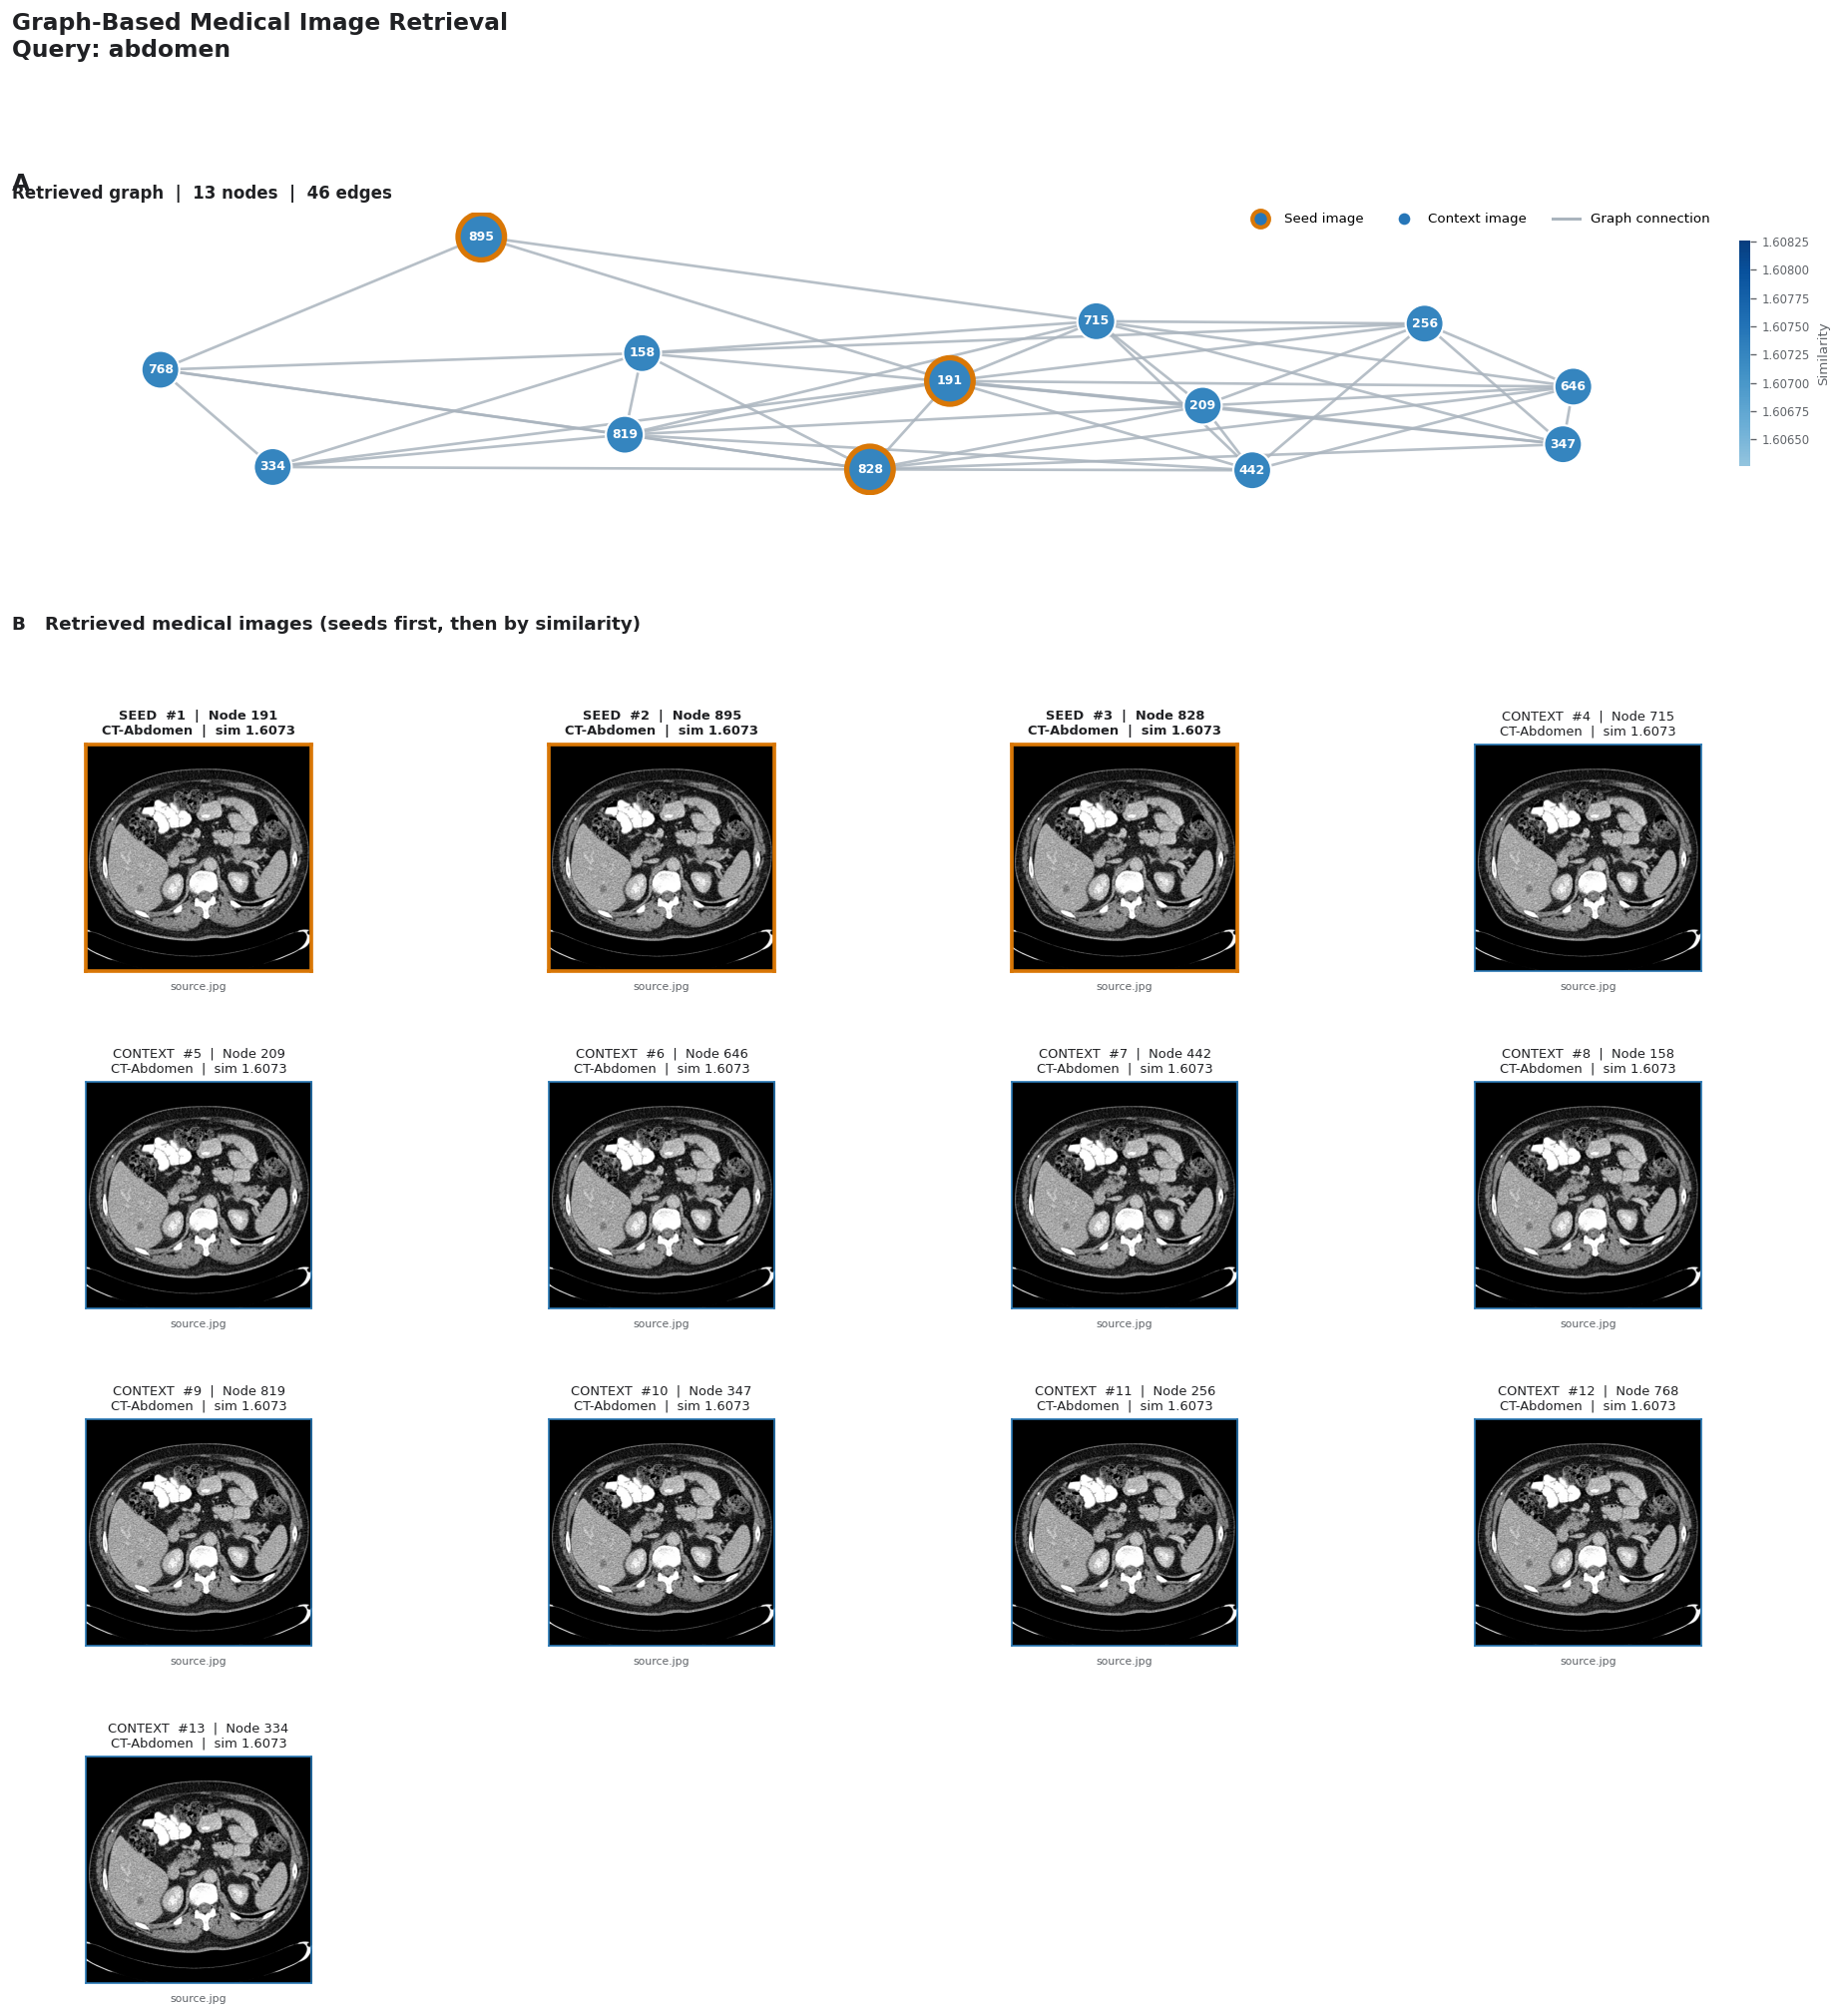 |
- madrisight/madrimed1.2-vision-embed works in conjunction with madrisight/madrimed1.2-text-embed to enable multimodal embedding alignment between medical images and text queries for semantic retrieval.
Intended Uses & Scope
Primary Intended Uses
- Visual Indexing for Clinical Graph RAG: Building knowledge graph topologies based on mutual $k$-nearest neighbors ($k$-NN) and cosine similarity.
- Radiological Case Retrieval: Identifying visually and structurally similar clinical scans across patient cohorts.
- Content-Based Image Retrieval (CBIR): Case-based reasoning support in hospital Picture Archiving and Communication Systems (PACS).
Out-of-Scope & Clinical Usage Constraints
- Primary Diagnostic Tool: This model produces vector representations for retrieval and clustering. It is not intended to provide standalone diagnostic determinations or replace certified radiologist review.
- Uncalibrated Similarity Thresholding: Due to visual anisotropy, embeddings should be mean-centered or hubness-corrected prior to static cosine thresholding to prevent high-degree hub formation.
Quickstart & Usage
Installation
pip install git+https://github.com/krrish-v/metalliger.git
Example Usage
import torch
from transformers import AutoProcessor, Qwen3VLVisionModel
from metalliger.utils.vison import func, GraphRAG
from metalliger.utils.text import TextEmbedder, EmbedderConfig
from PIL import Image

VISION_MODEL_DIR = "madrisight/madrimed1.2-vision-embed"
TEXT_MODEL_DIR = "madrisight/madrimed1.2-text-embed"

device = "cuda" if torch.cuda.is_available() else ("mps" if torch.backends.mps.is_available() else "cpu")

# Vision side (unchanged)
processor = AutoProcessor.from_pretrained(VISION_MODEL_DIR, trust_remote_code=True)
vision_model = Qwen3VLVisionModel.from_pretrained(
    VISION_MODEL_DIR, dtype=torch.float32, trust_remote_code=True,
).to(device).eval()

embedder = TextEmbedder(EmbedderConfig(model_dir=TEXT_MODEL_DIR, dtype=torch.float32))

vision_helper = func()
image_records = ["MM-25-e.jpeg", "MM-120-a.jpeg", "MM-7-e.jpeg"]
G, image_embeddings, latencies = vision_helper.similarity_graph(
    images=image_records, image_processor=processor, vision_model=vision_model, texts=None,
)

rag_service = GraphRAG()
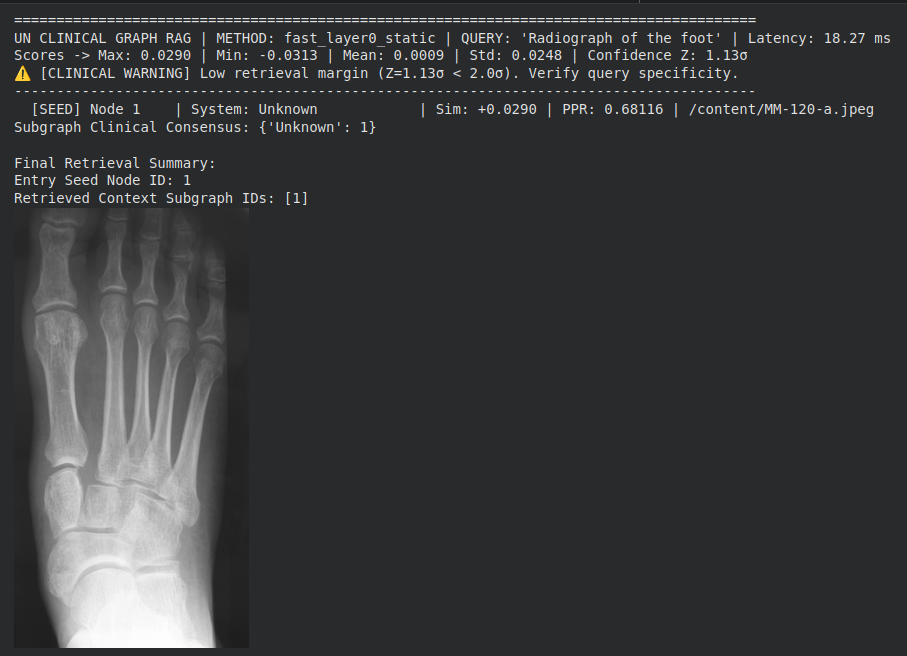
seed_nodes, retrieved_subgraph, smoothed_sims = rag_service.query_graph_rag_pure(
    text_query=text_query,
    embedder=embedder,
    G=G,
    img_embeddings=image_embeddings,
    top_k_seeds=3,
    k_neighbors=1,
    verbose=False,
)

print(f"Entry Seed Node ID: {seed_nodes[0]}")
print(f"Retrieved Context Subgraph IDs: {retrieved_subgraph}")

Image.open(G.nodes[seed_nodes[0]]["image"]).show()
Evaluation & Empirical Benchmarks
The visual representation quality was benchmarked using stratified multi-organ medical cohorts:
Medical Image Graph RAG
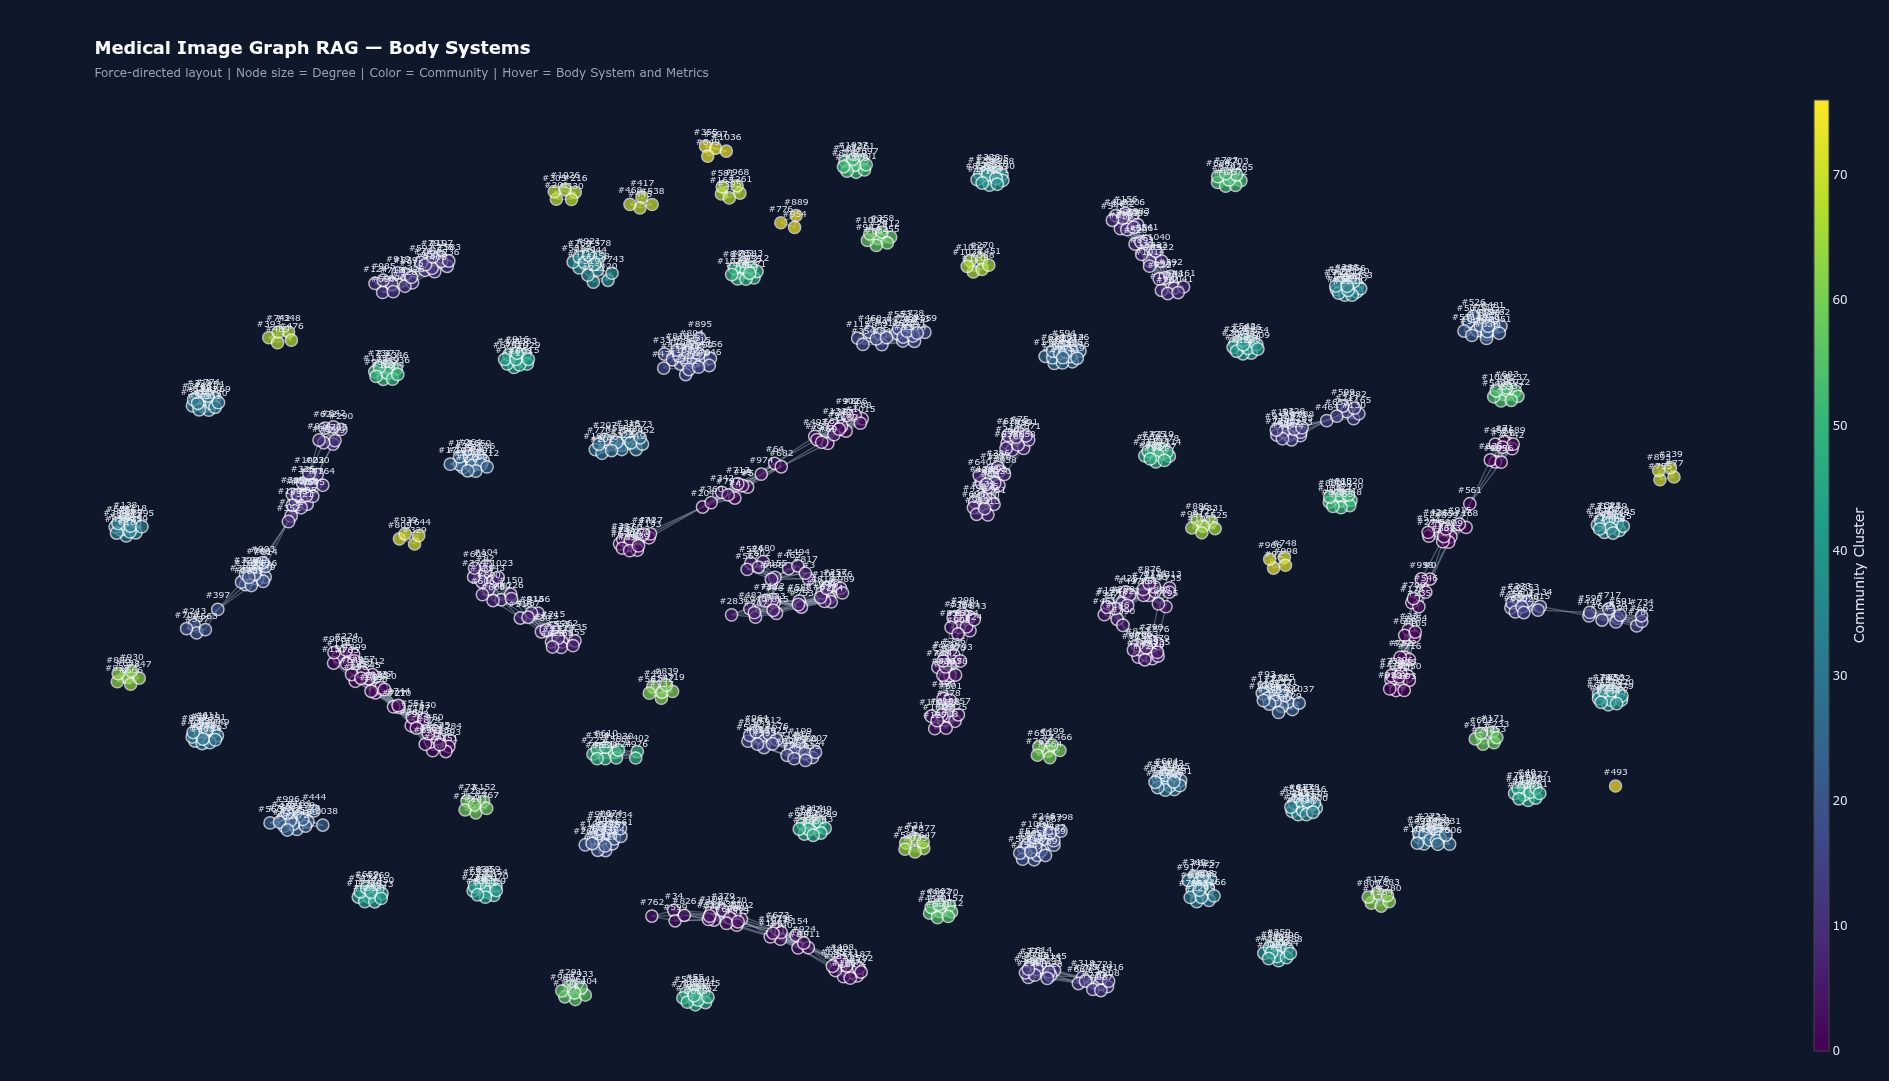
Vision Space Diagnostic
Graph Construction Guidelines
When deploying this model inside a Graph RAG or retrieval pipeline:
- Hubness Mitigation: Apply mean-centering ($\mathbf{e}_{\text{cal}} = \frac{\mathbf{e} - \boldsymbol{\mu}}{|\mathbf{e} - \boldsymbol{\mu}|_2}$) prior to distance calculation to mitigate the narrow-cone effect.
- Mutual $k$-NN Topology: Prefer mutual $k$-nearest neighbors ($k \in [6, 12]$) over flat static thresholding ($\tau = 0.85$) to prevent edge oversaturation across dominant modalities.
- Auditability: Generate deterministic SHA-256 digests over resized scan bytes to support PACS compliance and record provenance.
Citation
@software{madrimed1.2-vision-embed,
  title = {Madrimed 1.2 Vison Encoder},
  author = {Madrisight},
  year = {2026},
  url = {https://huggingface.co/madrisight/madrimed1.2-vision-embed}
}
- Downloads last month
- 160
Inference Providers NEW
This model isn't deployed by any Inference Provider. 🙋 Ask for provider support