

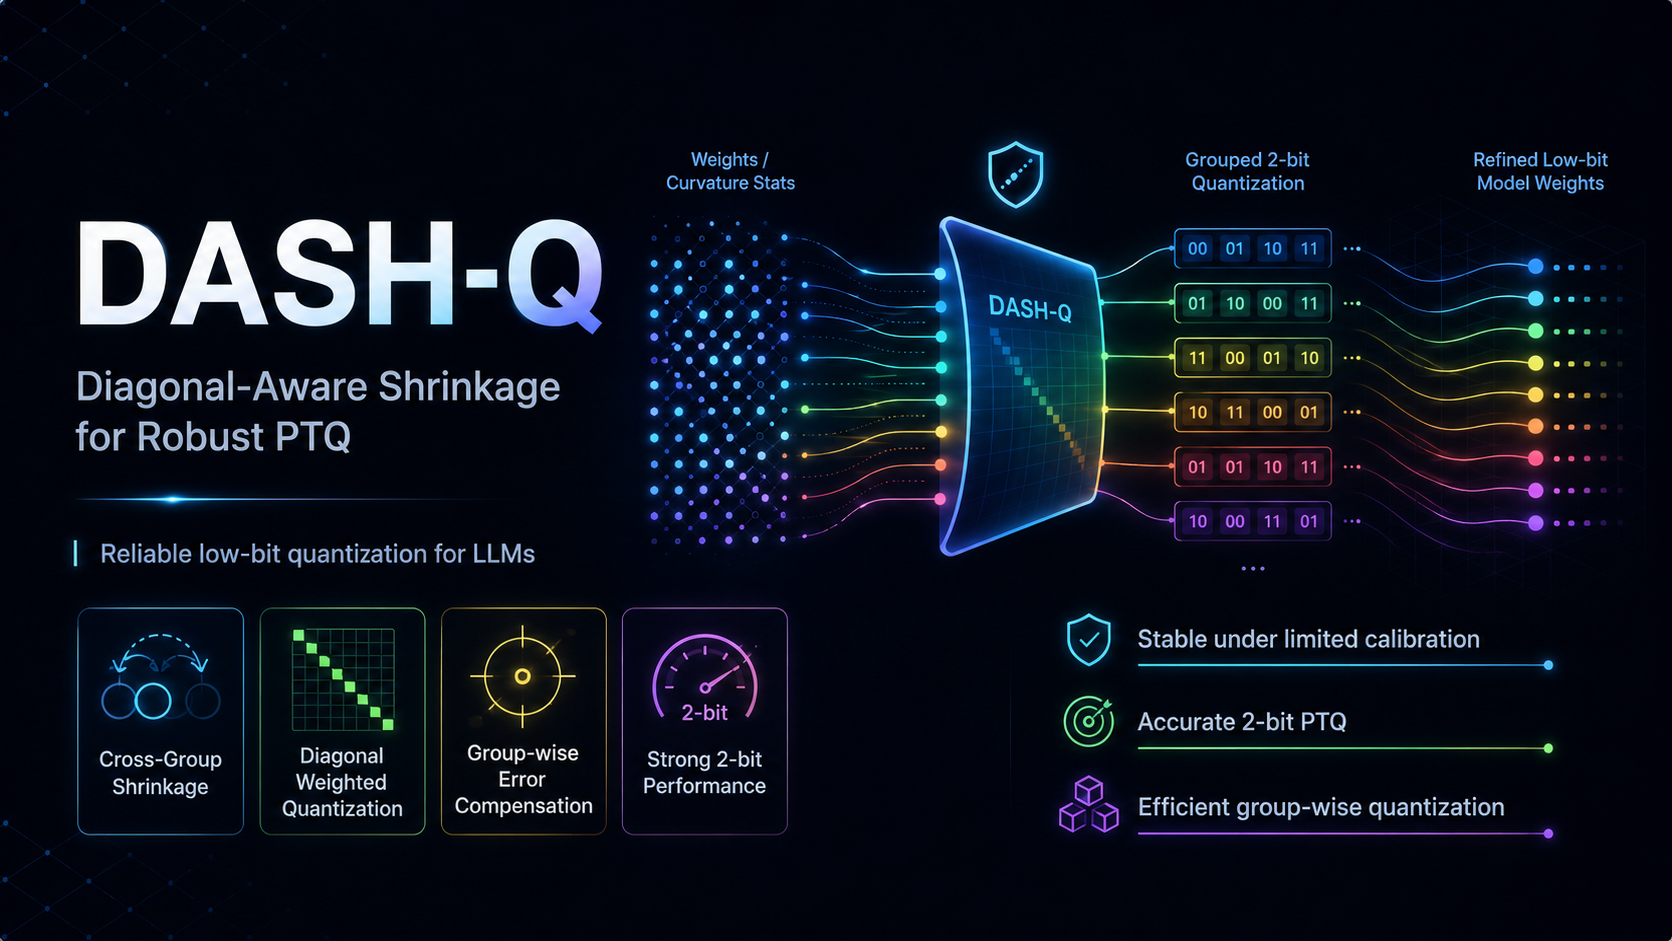
Seed-Coder-8B-Reasoning - DASH-Q 2-bit GGUF
llama.cpp GGUF files of ByteDance-Seed/Seed-Coder-8B-Reasoning quantized with DASH-Q, at several 2-bit-class sizes. Every file uses only standard llama.cpp tensor types (no tensor above 4 bits) and loads in any recent llama.cpp build.
| File | Type | Size | Bits / weight |
|---|---|---|---|
Seed-Coder-8B-Reasoning-DASHQ-IQ2_XXS.gguf |
IQ2_XXS | 2.65 GB | 2.57 |
Seed-Coder-8B-Reasoning-DASHQ-IQ2_XS.gguf |
IQ2_XS | 2.98 GB | 2.89 |
Seed-Coder-8B-Reasoning-DASHQ-IQ2_M.gguf |
IQ2_M | 3.13 GB | 3.04 |
Seed-Coder-8B-Reasoning-DASHQ-Q2_K_XL.gguf |
Q2_K_XL | 3.38 GB | 3.28 |
Perplexity (lower is better)
| Type | Model | Size | WikiText-2 | C4 |
|---|---|---|---|---|
| IQ2_XXS | llama.cpp IQ2_XXS (imatrix) | 2.51 GB | 32.46 | 40.64 |
| IQ2_XXS | unsloth UD-IQ2_XXS | 2.63 GB | 31.36 | 39.94 |
| IQ2_XXS | DASH-Q IQ2_XXS | 2.65 GB | 26.82 | 35.97 |
| IQ2_XS | llama.cpp IQ2_XS (imatrix) | 2.72 GB | 29.29 | 37.85 |
| IQ2_XS | DASH-Q IQ2_XS | 2.98 GB | 25.58 | 34.42 |
| IQ2_M | llama.cpp IQ2_M (imatrix) | 3.07 GB | 27.75 | 36.07 |
| IQ2_M | unsloth UD-IQ2_M | 3.13 GB | 27.17 | 36.04 |
| IQ2_M | DASH-Q IQ2_M | 3.13 GB | 25.15 | 34.05 |
| Q2_K_XL | llama.cpp Q2_K (imatrix) | 3.30 GB | 27.65 | 36.48 |
| Q2_K_XL | unsloth UD-Q2_K_XL | 3.54 GB | 25.38 | 33.95 |
| Q2_K_XL | DASH-Q Q2_K_XL | 3.38 GB | 24.81 | 33.48 |
llama-perplexity, context 2048; WikiText-2 test, C4 validation (256 x 2048 tokens).
Usage
llama-cli -m Seed-Coder-8B-Reasoning-DASHQ-Q2_K_XL.gguf -ngl 99 -c 8192
License
Inherits the license of the base model (ByteDance-Seed/Seed-Coder-8B-Reasoning).
- Downloads last month
- 230
Hardware compatibility
Log In to add your hardware
2-bit
Model tree for jkim96/Seed-Coder-8B-Reasoning-DASHQ-Q2-GGUF
Base model
ByteDance-Seed/Seed-Coder-8B-Base Finetuned
ByteDance-Seed/Seed-Coder-8B-Reasoning