


Upload folder using huggingface_hub
Browse files- .DS_Store +0 -0
- LICENSE.md +35 -0
- README.md +234 -2
- luxdit_image/.DS_Store +0 -0
- luxdit_image/.gitattributes +35 -0
- luxdit_image/config.json +1 -0
- luxdit_image/diffusion_pytorch_model.safetensors +3 -0
- luxdit_image/lora/.DS_Store +0 -0
- luxdit_image/lora/model.safetensors +3 -0
- luxdit_video/.gitattributes +35 -0
- luxdit_video/config.json +1 -0
- luxdit_video/diffusion_pytorch_model.safetensors +3 -0
- luxdit_video/lora/model.safetensors +3 -0
.DS_Store
ADDED
|
Binary file (8.2 kB). View file
|
|
|
LICENSE.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# NVIDIA OneWay Noncommercial License
|
| 2 |
+
|
| 3 |
+
## 1. Definitions
|
| 4 |
+
|
| 5 |
+
“Licensor” means any person or entity that distributes its Work.
|
| 6 |
+
“Work” means (a) the original work of authorship made available under this license, which may include software, documentation, or other files, and (b) any additions to or derivative works thereof that are made available under this license.
|
| 7 |
+
The terms “reproduce,” “reproduction,” “derivative works,” and “distribution” have the meaning as provided under U.S. copyright law; provided, however, that for the purposes of this license, derivative works shall not include works that remain separable from, or merely link (or bind by name) to the interfaces of, the Work.
|
| 8 |
+
Works are “made available” under this license by including in or with the Work either (a) a copyright notice referencing the applicability of this license to the Work, or (b) a copy of this license.
|
| 9 |
+
|
| 10 |
+
## 2. License Grant
|
| 11 |
+
|
| 12 |
+
2.1 Copyright Grant. Subject to the terms and conditions of this license, each Licensor grants to you a perpetual, worldwide, non-exclusive, royalty-free, copyright license to use, reproduce, prepare derivative works of, publicly display, publicly perform, sublicense and distribute its Work and any resulting derivative works in any form.
|
| 13 |
+
|
| 14 |
+
## 3. Limitations
|
| 15 |
+
|
| 16 |
+
3.1 Redistribution. You may reproduce or distribute the Work only if (a) you do so under this license, (b) you include a complete copy of this license with your distribution, and (c) you retain without modification any copyright, patent, trademark, or attribution notices that are present in the Work.
|
| 17 |
+
|
| 18 |
+
3.2 Derivative Works. You may specify that additional or different terms apply to the use, reproduction, and distribution of your derivative works of the Work (“Your Terms”) only if (a) Your Terms provide that the use limitation in Section 3.3 applies to your derivative works, and (b) you identify the specific derivative works that are subject to Your Terms. Notwithstanding Your Terms, this license (including the redistribution requirements in Section 3.1) will continue to apply to the Work itself.
|
| 19 |
+
|
| 20 |
+
3.3 Use Limitation. The Work and any derivative works thereof only may be used or intended for use non-commercially. Notwithstanding the foregoing, NVIDIA Corporation and its affiliates may use the Work and any derivative works commercially. As used herein, “non-commercially” means for research or evaluation purposes only.
|
| 21 |
+
|
| 22 |
+
3.4 Patent Claims. If you bring or threaten to bring a patent claim against any Licensor (including any claim, cross-claim or counterclaim in a lawsuit) to enforce any patents that you allege are infringed by any Work, then your rights under this license from such Licensor (including the grant in Section 2.1) will terminate immediately.
|
| 23 |
+
|
| 24 |
+
3.5 Trademarks. This license does not grant any rights to use any Licensor’s or its affiliates’ names, logos, or trademarks, except as necessary to reproduce the notices described in this license.
|
| 25 |
+
|
| 26 |
+
3.6 Termination. If you violate any term of this license, then your rights under this license (including the grant in Section 2.1) will terminate immediately.
|
| 27 |
+
|
| 28 |
+
## 4. Disclaimer of Warranty.
|
| 29 |
+
|
| 30 |
+
THE WORK IS PROVIDED “AS IS” WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, EITHER EXPRESS OR IMPLIED, INCLUDING WARRANTIES OR CONDITIONS OF
|
| 31 |
+
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, TITLE OR NON-INFRINGEMENT. YOU BEAR THE RISK OF UNDERTAKING ANY ACTIVITIES UNDER THIS LICENSE.
|
| 32 |
+
|
| 33 |
+
## 5. Limitation of Liability.
|
| 34 |
+
|
| 35 |
+
EXCEPT AS PROHIBITED BY APPLICABLE LAW, IN NO EVENT AND UNDER NO LEGAL THEORY, WHETHER IN TORT (INCLUDING NEGLIGENCE), CONTRACT, OR OTHERWISE SHALL ANY LICENSOR BE LIABLE TO YOU FOR DAMAGES, INCLUDING ANY DIRECT, INDIRECT, SPECIAL, INCIDENTAL, OR CONSEQUENTIAL DAMAGES ARISING OUT OF OR RELATED TO THIS LICENSE, THE USE OR INABILITY TO USE THE WORK (INCLUDING BUT NOT LIMITED TO LOSS OF GOODWILL, BUSINESS INTERRUPTION, LOST PROFITS OR DATA, COMPUTER FAILURE OR MALFUNCTION, OR ANY OTHER DAMAGES OR LOSSES), EVEN IF THE LICENSOR HAS BEEN ADVISED OF THE POSSIBILITY OF SUCH DAMAGES.
|
README.md
CHANGED
|
@@ -1,5 +1,237 @@
|
|
| 1 |
---
|
| 2 |
license: other
|
| 3 |
-
|
| 4 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 5 |
---
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
---
|
| 2 |
license: other
|
| 3 |
+
license_link: LICENSE.md
|
| 4 |
+
tags:
|
| 5 |
+
- lighting-estimation
|
| 6 |
+
- hdr
|
| 7 |
+
- environment-map
|
| 8 |
+
- diffusion
|
| 9 |
+
- pytorch
|
| 10 |
+
- video
|
| 11 |
+
- transformer
|
| 12 |
+
- lora
|
| 13 |
---
|
| 14 |
+
|
| 15 |
+
# LuxDiT
|
| 16 |
+
|
| 17 |
+
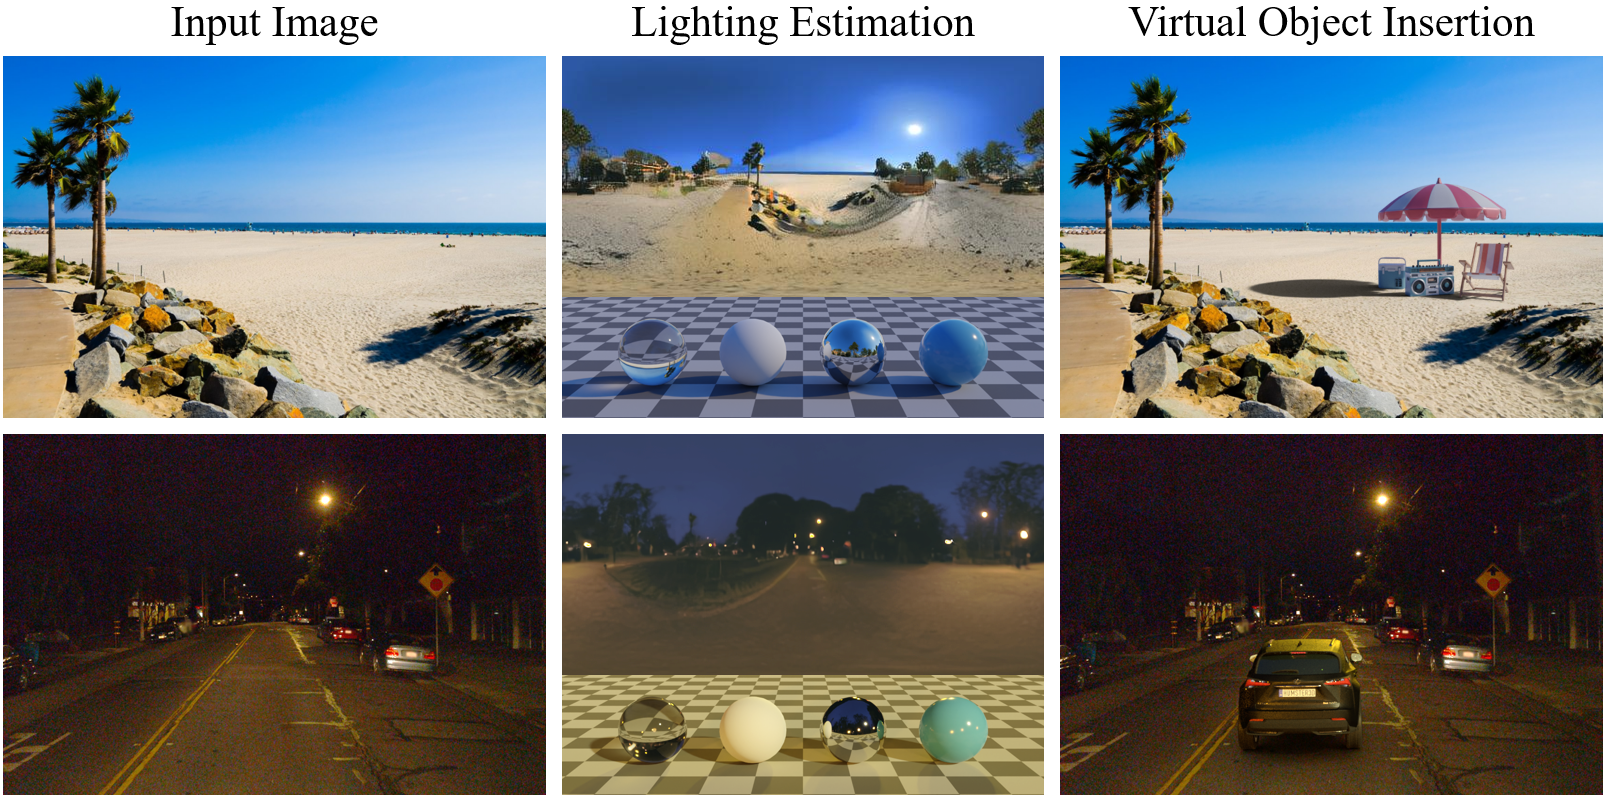
This is the model checkpoint for [LuxDiT](https://github.com/nv-tlabs/LuxDiT): Lighting Estimation with Video Diffusion Transformer. It is finetuned on image data and includes a LoRA adapter for real scenes.
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
## Model description
|
| 22 |
+
|
| 23 |
+
LuxDiT is a generative lighting estimation model that predicts high-quality HDR environment maps from visual input. It produces accurate lighting while preserving scene semantics, enabling realistic virtual object insertion under diverse lighting conditions. This model is ready for non-commercial use.
|
| 24 |
+
|
| 25 |
+
- **Checkpoint**: Video model (image and video-finetuned)
|
| 26 |
+
- **LoRA**: Included for real-scene generalization
|
| 27 |
+
- **Paper**: [LuxDiT: Lighting Estimation with Video Diffusion Transformer](https://arxiv.org/abs/2509.03680)
|
| 28 |
+
- **Project page**: https://research.nvidia.com/labs/toronto-ai/LuxDiT/
|
| 29 |
+
|
| 30 |
+
**Use case:** LuxDiT supports studies and prototyping in video lighting estimation. This release is an open-source implementation of our research paper, intended for AI research, development, and benchmarking for lighting estimation research.
|
| 31 |
+
|
| 32 |
+
### Model architecture
|
| 33 |
+
|
| 34 |
+
- **Architecture type:** Transformer (based on [CogVideoX](https://github.com/THUDM/CogVideoX))
|
| 35 |
+
- **Parameters:** 5B
|
| 36 |
+
- **Input:** RGB video frames; shape `[batch_size, num_frames, height, width, 3]`; recommended resolution 480×720
|
| 37 |
+
- **Output:** RGB video frames (dual tonemapped LDR and log); output resolution 256×512; use the HDR merger to obtain `.exr` HDR envmaps
|
| 38 |
+
|
| 39 |
+
### Software and hardware
|
| 40 |
+
|
| 41 |
+
- **Runtime:** Python and PyTorch
|
| 42 |
+
- **Supported hardware:** NVIDIA Ampere (e.g. A100 GPUs)
|
| 43 |
+
- **Operating system:** Linux
|
| 44 |
+
|
| 45 |
+
## How to use
|
| 46 |
+
|
| 47 |
+
### Download from Hugging Face
|
| 48 |
+
|
| 49 |
+
From the [LuxDiT repository](https://github.com/nv-tlabs/LuxDiT) root:
|
| 50 |
+
|
| 51 |
+
```bash
|
| 52 |
+
python download_weights.py --repo_id <HF_ORG>/LuxDiT
|
| 53 |
+
```
|
| 54 |
+
|
| 55 |
+
This saves the checkpoint to `checkpoints/LuxDiT` by default. Use `--local_dir` to override.
|
| 56 |
+
|
| 57 |
+
### Image Inference: synthetic images (in-domain)
|
| 58 |
+
|
| 59 |
+
```bash
|
| 60 |
+
DIT_PATH=checkpoints/LuxDiT/luxdit_image
|
| 61 |
+
INPUT_DIR=examples/input_demo/synthetic_images
|
| 62 |
+
OUTPUT_DIR=test_output/synthetic_images
|
| 63 |
+
|
| 64 |
+
python inference_luxdit.py \
|
| 65 |
+
--config configs/luxdit_base.yaml \
|
| 66 |
+
--transformer_path $DIT_PATH \
|
| 67 |
+
--input_dir $INPUT_DIR \
|
| 68 |
+
--output_dir $OUTPUT_DIR \
|
| 69 |
+
--resolution 480 720 \
|
| 70 |
+
--guidance_scale 2.5 \
|
| 71 |
+
--num_inference_steps 50 \
|
| 72 |
+
--seed 33
|
| 73 |
+
|
| 74 |
+
python hdr_merger.py \
|
| 75 |
+
--model_path checkpoints/hdr_merge_mlp \
|
| 76 |
+
--input_dir $OUTPUT_DIR/ldr_log \
|
| 77 |
+
--output_dir $OUTPUT_DIR/hdr
|
| 78 |
+
```
|
| 79 |
+
|
| 80 |
+
### Image Inference: real scenes (with LoRA)
|
| 81 |
+
|
| 82 |
+
Use the LoRA adapter in this checkpoint for better generalization to real photos:
|
| 83 |
+
|
| 84 |
+
```bash
|
| 85 |
+
DIT_PATH=checkpoints/LuxDiT/luxdit_image
|
| 86 |
+
LORA_PATH=checkpoints/luxdit_image/lora
|
| 87 |
+
INPUT_DIR=examples/input_demo/scene_images
|
| 88 |
+
OUTPUT_DIR=test_output/scene_images
|
| 89 |
+
|
| 90 |
+
python inference_luxdit.py \
|
| 91 |
+
--config configs/luxdit_base.yaml \
|
| 92 |
+
--transformer_path $DIT_PATH \
|
| 93 |
+
--lora_dir $LORA_PATH \
|
| 94 |
+
--lora_scale 0.8 \
|
| 95 |
+
--input_dir $INPUT_DIR \
|
| 96 |
+
--output_dir $OUTPUT_DIR \
|
| 97 |
+
--resolution 480 720 \
|
| 98 |
+
--guidance_scale 2.5 \
|
| 99 |
+
--num_inference_steps 50 \
|
| 100 |
+
--seed 33
|
| 101 |
+
|
| 102 |
+
python hdr_merger.py \
|
| 103 |
+
--input_dir $OUTPUT_DIR/ldr_log \
|
| 104 |
+
--output_dir $OUTPUT_DIR/hdr
|
| 105 |
+
```
|
| 106 |
+
|
| 107 |
+
Adjust `lora_scale` (e.g. 0.0–1.0) to control how much the input scene is merged into the estimated envmap.
|
| 108 |
+
|
| 109 |
+
|
| 110 |
+
### Video Inference: synthetic videos (in-domain)
|
| 111 |
+
|
| 112 |
+
Requires `--data_type video`:
|
| 113 |
+
|
| 114 |
+
```bash
|
| 115 |
+
DIT_PATH=checkpoints/LuxDiT/luxdit_video
|
| 116 |
+
INPUT_DIR=examples/input_demo/synthetic_videos
|
| 117 |
+
OUTPUT_DIR=test_output/synthetic_videos
|
| 118 |
+
|
| 119 |
+
python inference_luxdit.py \
|
| 120 |
+
--config configs/luxdit_base.yaml \
|
| 121 |
+
--transformer_path $DIT_PATH \
|
| 122 |
+
--input_dir $INPUT_DIR \
|
| 123 |
+
--output_dir $OUTPUT_DIR \
|
| 124 |
+
--resolution 480 720 \
|
| 125 |
+
--guidance_scale 2.5 \
|
| 126 |
+
--num_inference_steps 40 \
|
| 127 |
+
--seed 33 \
|
| 128 |
+
--data_type video
|
| 129 |
+
|
| 130 |
+
python hdr_merger.py \
|
| 131 |
+
--input_dir $OUTPUT_DIR/ldr_log \
|
| 132 |
+
--output_dir $OUTPUT_DIR/hdr
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
### Video Inference: real scenes from video (with LoRA)
|
| 136 |
+
|
| 137 |
+
Use the LoRA adapter in this checkpoint for better generalization to real video:
|
| 138 |
+
|
| 139 |
+
```bash
|
| 140 |
+
DIT_PATH=checkpoints/LuxDiT/luxdit_video
|
| 141 |
+
LORA_PATH=checkpoints/LuxDiT/luxdit_video/lora
|
| 142 |
+
INPUT_DIR=examples/input_demo/scene_videos
|
| 143 |
+
OUTPUT_DIR=test_output/scene_videos
|
| 144 |
+
|
| 145 |
+
python inference_luxdit.py \
|
| 146 |
+
--config configs/luxdit_base.yaml \
|
| 147 |
+
--transformer_path $DIT_PATH \
|
| 148 |
+
--lora_dir $LORA_PATH \
|
| 149 |
+
--lora_scale 0.8 \
|
| 150 |
+
--input_dir $INPUT_DIR \
|
| 151 |
+
--output_dir $OUTPUT_DIR \
|
| 152 |
+
--resolution 480 720 \
|
| 153 |
+
--guidance_scale 2.5 \
|
| 154 |
+
--num_inference_steps 40 \
|
| 155 |
+
--seed 33 \
|
| 156 |
+
--data_type video
|
| 157 |
+
|
| 158 |
+
python hdr_merger.py \
|
| 159 |
+
--input_dir $OUTPUT_DIR/ldr_log \
|
| 160 |
+
--output_dir $OUTPUT_DIR/hdr
|
| 161 |
+
```
|
| 162 |
+
|
| 163 |
+
Adjust `lora_scale` (e.g. 0.0–1.0) to control how much the input scene is merged into the estimated envmap.
|
| 164 |
+
|
| 165 |
+
### Inference: object video scan with camera poses
|
| 166 |
+
|
| 167 |
+
For multi-view object captures, you can optionally provide camera poses (`--camera_pose_file`, OpenCV format) to align the estimated envmap to a canonical layout:
|
| 168 |
+
|
| 169 |
+
```bash
|
| 170 |
+
DIT_PATH=checkpoints/LuxDiT/luxdit_video
|
| 171 |
+
LORA_PATH=checkpoints/LuxDiT/luxdit_video/lora
|
| 172 |
+
INPUT_DIR=examples/input_demo/object_scans/antman
|
| 173 |
+
OUTPUT_DIR=test_output/object_scans/antman
|
| 174 |
+
CAM_FILE=examples/input_demo/object_scans/antman/antman.camera.json
|
| 175 |
+
|
| 176 |
+
python inference_luxdit.py \
|
| 177 |
+
--config configs/luxdit_base.yaml \
|
| 178 |
+
--transformer_path $DIT_PATH \
|
| 179 |
+
--lora_dir $LORA_PATH \
|
| 180 |
+
--lora_scale 0.0 \
|
| 181 |
+
--input_dir $INPUT_DIR \
|
| 182 |
+
--output_dir $OUTPUT_DIR \
|
| 183 |
+
--resolution 512 512 \
|
| 184 |
+
--guidance_scale 2.5 \
|
| 185 |
+
--num_inference_steps 40 \
|
| 186 |
+
--seed 33 \
|
| 187 |
+
--data_type video \
|
| 188 |
+
--camera_pose_file $CAM_FILE
|
| 189 |
+
|
| 190 |
+
python hdr_merger.py \
|
| 191 |
+
--input_dir $OUTPUT_DIR/ldr_log \
|
| 192 |
+
--output_dir $OUTPUT_DIR/hdr
|
| 193 |
+
```
|
| 194 |
+
|
| 195 |
+
## Related checkpoints
|
| 196 |
+
|
| 197 |
+
| Checkpoint | Description |
|
| 198 |
+
|-------------|-------------|
|
| 199 |
+
| [luxdit_image](https://huggingface.co/nvidia/LuxDiT/luxdit_image) | Image-finetuned, with LoRA for real scenes |
|
| 200 |
+
| [luxdit_video](https://huggingface.co/nvidia/LuxDiT/luxdit_video) | Video-finetuned, with LoRA for real scenes |
|
| 201 |
+
|
| 202 |
+
For video inputs and object scans, use **luxdit_video** instead.
|
| 203 |
+
|
| 204 |
+
## Training data
|
| 205 |
+
|
| 206 |
+
This checkpoint is video-finetuned on the **SyntheticScenes** dataset:
|
| 207 |
+
|
| 208 |
+
- **Modality:** Video
|
| 209 |
+
- **Scale:** ~108,000 rendered videos; each video has 57 frames at 704×1280 resolution
|
| 210 |
+
- **Collection:** Synthetic data generated with an OptiX-based physically based path tracer
|
| 211 |
+
- **Labels:** Produced by the renderer (no manual labeling)
|
| 212 |
+
- **Per sample:** Input RGB (LDR) video and HDR environment lighting
|
| 213 |
+
|
| 214 |
+
Testing and evaluation use held-out 10% splits of the same dataset.
|
| 215 |
+
|
| 216 |
+
## Output format
|
| 217 |
+
|
| 218 |
+
The model outputs dual tonemapped environment maps (LDR and log); use the HDR merger to get `.exr` HDR envmaps. By default, the camera pose of the input image defines the world frame. See the [main README](https://github.com/NVIDIA/LuxDiT#output-format) for the exact layout of LDR/log vs merged HDR.
|
| 219 |
+
|
| 220 |
+
## Ethical considerations
|
| 221 |
+
|
| 222 |
+
NVIDIA believes Trustworthy AI is a shared responsibility. When using this model in accordance with the terms of service, ensure it meets requirements for your use case and addresses potential misuse. You are responsible for having proper rights and permissions for all input image and video content; if content includes people, personal health information, or intellectual property, generated outputs will not blur or preserve proportions of subjects. Users are responsible for model inputs and outputs and for implementing appropriate guardrails and safety mechanisms before deployment. To report model quality, risk, security vulnerabilities, or other concerns, see [NVIDIA AI Concerns](https://app.intigriti.com/programs/nvidia/nvidiavdp/detail).
|
| 223 |
+
|
| 224 |
+
## License
|
| 225 |
+
|
| 226 |
+
NVIDIA OneWay Noncommercial License. See the [LICENSE](LICENSE.md) in the LuxDiT repository.
|
| 227 |
+
|
| 228 |
+
## Citation
|
| 229 |
+
|
| 230 |
+
```bibtex
|
| 231 |
+
@article{liang2025luxdit,
|
| 232 |
+
title={Luxdit: Lighting estimation with video diffusion transformer},
|
| 233 |
+
author={Liang, Ruofan and He, Kai and Gojcic, Zan and Gilitschenski, Igor and Fidler, Sanja and Vijaykumar, Nandita and Wang, Zian},
|
| 234 |
+
journal={arXiv preprint arXiv:2509.03680},
|
| 235 |
+
year={2025}
|
| 236 |
+
}
|
| 237 |
+
```
|
luxdit_image/.DS_Store
ADDED
|
Binary file (6.15 kB). View file
|
|
|
luxdit_image/.gitattributes
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
luxdit_image/config.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"_class_name": "CustomCogVideoXTransformer3DModel", "_diffusers_version": "0.32.1", "_name_or_path": "THUDM/CogVideoX-5b-I2V", "activation_fn": "gelu-approximate", "additional_output_channels": 32, "additional_patch_embed_channels": 48, "attention_bias": true, "attention_head_dim": 64, "dropout": 0.0, "flip_sin_to_cos": true, "freq_shift": 0, "in_channels": 16, "max_text_seq_length": 226, "norm_elementwise_affine": true, "norm_eps": 1e-05, "num_attention_heads": 48, "num_layers": 42, "ofs_embed_dim": null, "out_channels": 16, "patch_bias": true, "patch_size": 2, "patch_size_t": null, "sample_frames": 49, "sample_height": 60, "sample_width": 90, "spatial_interpolation_scale": 1.875, "temporal_compression_ratio": 4, "temporal_interpolation_scale": 1.0, "text_embed_dim": 4096, "time_embed_dim": 512, "timestep_activation_fn": "silu", "use_fixed_pos_embedding": false, "use_learned_positional_embeddings": false, "use_positional_embeddings": false, "use_rotary_positional_embeddings": true}
|
luxdit_image/diffusion_pytorch_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:14373cebcb5b05880eba20b5015cd938adb65d9871131bfedcca237a724cceea
|
| 3 |
+
size 11148972264
|
luxdit_image/lora/.DS_Store
ADDED
|
Binary file (6.15 kB). View file
|
|
|
luxdit_image/lora/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ec8410c0f6bc11f070c7f516e49ebfdd28d6a3dd3a39959abb5ed25747a2f7bb
|
| 3 |
+
size 594609352
|
luxdit_video/.gitattributes
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
luxdit_video/config.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"_class_name": "CustomCogVideoXTransformer3DModel", "_diffusers_version": "0.32.1", "_name_or_path": "THUDM/CogVideoX-5b-I2V", "activation_fn": "gelu-approximate", "additional_output_channels": 32, "additional_patch_embed_channels": 48, "attention_bias": true, "attention_head_dim": 64, "dropout": 0.0, "flip_sin_to_cos": true, "freq_shift": 0, "in_channels": 16, "max_text_seq_length": 226, "norm_elementwise_affine": true, "norm_eps": 1e-05, "num_attention_heads": 48, "num_layers": 42, "ofs_embed_dim": null, "out_channels": 16, "patch_bias": true, "patch_size": 2, "patch_size_t": null, "sample_frames": 49, "sample_height": 60, "sample_width": 90, "spatial_interpolation_scale": 1.875, "temporal_compression_ratio": 4, "temporal_interpolation_scale": 1.0, "text_embed_dim": 4096, "time_embed_dim": 512, "timestep_activation_fn": "silu", "use_fixed_pos_embedding": false, "use_learned_positional_embeddings": false, "use_positional_embeddings": false, "use_rotary_positional_embeddings": true}
|
luxdit_video/diffusion_pytorch_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:fb1fe4b81b0d2f70c55088093553ea826adba06203168295a49d8ae54dae5a08
|
| 3 |
+
size 11148972264
|
luxdit_video/lora/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:bed86768b8b6b285697217f860baa5658ce81e41082fb17df6c6009dbbcb8d08
|
| 3 |
+
size 594609352
|