


Commit ·
c44f870
0
Parent(s):
Duplicate from Ujjwal-Tyagi/ai-ml-foundations-book-collection
Browse filesCo-authored-by: Ujjwal Tyagi <Ujjwal-Tyagi@users.noreply.huggingface.co>
- .gitattributes +85 -0
- AI Engineering Guidebook.pdf +3 -0
- Algorithms for Decision Making.pdf +3 -0
- Algorithms for Optimization.pdf +3 -0
- Algorithms for Validation.pdf +3 -0
- Bishop-Pattern-Recognition-and-Machine-Learning.pdf +3 -0
- Build-a-large-language-models.pdf +3 -0
- Convex Optimization.pdf +3 -0
- Deep Learning with Python.pdf +3 -0
- Foundations of Machine Learning.pdf +3 -0
- Information Theory, Inference, and Learning Algorithms.pdf +3 -0
- Introduction to Machine Learning - Nils.pdf +3 -0
- Machine-Learning-from-Human-Preferences.pdf +3 -0
- Natural Language Processing with Transformers Building Language Applications with Hugging Face by Lewis Tunstall Leandro von Werra Thomas Wolf.pdf +3 -0
- Probabilistic Machine Learning - Advanced Topics.pdf +3 -0
- README.md +962 -0
- RL - An Introduction.pdf +3 -0
- The Elements of Statistical Learning.pdf +3 -0
- The Principles of Deep Learning Theory.pdf +3 -0
- Understanding Deep Learning.pdf +3 -0
- book0 - A Probabilistic Perspective.pdf +3 -0
- book1 - Probabilistic Machine Learning - An Introduction.pdf +3 -0
- fairmlbook.pdf +3 -0
- marl-book.pdf +3 -0
- mml-book.pdf +3 -0
- natural-language-processing-with-transformers.pdf +3 -0
- understanding-machine-learning-theory-algorithms.pdf +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,85 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.avro filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.lz4 filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.mds filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
# Audio files - uncompressed
|
| 40 |
+
*.pcm filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
*.sam filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
*.raw filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
# Audio files - compressed
|
| 44 |
+
*.aac filter=lfs diff=lfs merge=lfs -text
|
| 45 |
+
*.flac filter=lfs diff=lfs merge=lfs -text
|
| 46 |
+
*.mp3 filter=lfs diff=lfs merge=lfs -text
|
| 47 |
+
*.ogg filter=lfs diff=lfs merge=lfs -text
|
| 48 |
+
*.wav filter=lfs diff=lfs merge=lfs -text
|
| 49 |
+
# Image files - uncompressed
|
| 50 |
+
*.bmp filter=lfs diff=lfs merge=lfs -text
|
| 51 |
+
*.gif filter=lfs diff=lfs merge=lfs -text
|
| 52 |
+
*.png filter=lfs diff=lfs merge=lfs -text
|
| 53 |
+
*.tiff filter=lfs diff=lfs merge=lfs -text
|
| 54 |
+
# Image files - compressed
|
| 55 |
+
*.jpg filter=lfs diff=lfs merge=lfs -text
|
| 56 |
+
*.jpeg filter=lfs diff=lfs merge=lfs -text
|
| 57 |
+
*.webp filter=lfs diff=lfs merge=lfs -text
|
| 58 |
+
# Video files - compressed
|
| 59 |
+
*.mp4 filter=lfs diff=lfs merge=lfs -text
|
| 60 |
+
*.webm filter=lfs diff=lfs merge=lfs -text
|
| 61 |
+
AI[[:space:]]Engineering[[:space:]]Guidebook.pdf filter=lfs diff=lfs merge=lfs -text
|
| 62 |
+
Algorithms[[:space:]]for[[:space:]]Decision[[:space:]]Making.pdf filter=lfs diff=lfs merge=lfs -text
|
| 63 |
+
Algorithms[[:space:]]for[[:space:]]Optimization.pdf filter=lfs diff=lfs merge=lfs -text
|
| 64 |
+
Algorithms[[:space:]]for[[:space:]]Validation.pdf filter=lfs diff=lfs merge=lfs -text
|
| 65 |
+
Bishop-Pattern-Recognition-and-Machine-Learning.pdf filter=lfs diff=lfs merge=lfs -text
|
| 66 |
+
book0[[:space:]]-[[:space:]]A[[:space:]]Probabilistic[[:space:]]Perspective.pdf filter=lfs diff=lfs merge=lfs -text
|
| 67 |
+
book1[[:space:]]-[[:space:]]Probabilistic[[:space:]]Machine[[:space:]]Learning[[:space:]]-[[:space:]]An[[:space:]]Introduction.pdf filter=lfs diff=lfs merge=lfs -text
|
| 68 |
+
Build-a-large-language-models.pdf filter=lfs diff=lfs merge=lfs -text
|
| 69 |
+
Convex[[:space:]]Optimization.pdf filter=lfs diff=lfs merge=lfs -text
|
| 70 |
+
Deep[[:space:]]Learning[[:space:]]with[[:space:]]Python.pdf filter=lfs diff=lfs merge=lfs -text
|
| 71 |
+
fairmlbook.pdf filter=lfs diff=lfs merge=lfs -text
|
| 72 |
+
Foundations[[:space:]]of[[:space:]]Machine[[:space:]]Learning.pdf filter=lfs diff=lfs merge=lfs -text
|
| 73 |
+
Information[[:space:]]Theory,[[:space:]]Inference,[[:space:]]and[[:space:]]Learning[[:space:]]Algorithms.pdf filter=lfs diff=lfs merge=lfs -text
|
| 74 |
+
marl-book.pdf filter=lfs diff=lfs merge=lfs -text
|
| 75 |
+
mml-book.pdf filter=lfs diff=lfs merge=lfs -text
|
| 76 |
+
Natural[[:space:]]Language[[:space:]]Processing[[:space:]]with[[:space:]]Transformers[[:space:]]Building[[:space:]]Language[[:space:]]Applications[[:space:]]with[[:space:]]Hugging[[:space:]]Face[[:space:]]by[[:space:]]Lewis[[:space:]]Tunstall[[:space:]][[:space:]]Leandro[[:space:]]von[[:space:]]Werra[[:space:]][[:space:]]Thomas[[:space:]]Wolf.pdf filter=lfs diff=lfs merge=lfs -text
|
| 77 |
+
Probabilistic[[:space:]]Machine[[:space:]]Learning[[:space:]]-[[:space:]]Advanced[[:space:]]Topics.pdf filter=lfs diff=lfs merge=lfs -text
|
| 78 |
+
RL[[:space:]]-[[:space:]]An[[:space:]]Introduction.pdf filter=lfs diff=lfs merge=lfs -text
|
| 79 |
+
The[[:space:]]Principles[[:space:]]of[[:space:]]Deep[[:space:]]Learning[[:space:]]Theory.pdf filter=lfs diff=lfs merge=lfs -text
|
| 80 |
+
Understanding[[:space:]]Deep[[:space:]]Learning.pdf filter=lfs diff=lfs merge=lfs -text
|
| 81 |
+
understanding-machine-learning-theory-algorithms.pdf filter=lfs diff=lfs merge=lfs -text
|
| 82 |
+
Introduction[[:space:]]to[[:space:]]Machine[[:space:]]Learning[[:space:]]-[[:space:]]Nils.pdf filter=lfs diff=lfs merge=lfs -text
|
| 83 |
+
Machine-Learning-from-Human-Preferences.pdf filter=lfs diff=lfs merge=lfs -text
|
| 84 |
+
natural-language-processing-with-transformers.pdf filter=lfs diff=lfs merge=lfs -text
|
| 85 |
+
The[[:space:]]Elements[[:space:]]of[[:space:]]Statistical[[:space:]]Learning.pdf filter=lfs diff=lfs merge=lfs -text
|
AI Engineering Guidebook.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1273e50aceb06a003d5440c3713a9902c9dc0c8b4c86694ce64d324ae79eae2c
|
| 3 |
+
size 95382738
|
Algorithms for Decision Making.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:297196f2cad5ab23cf4855f815fd69e7b7b9ee9c31255f743b668416677ad24e
|
| 3 |
+
size 12111874
|
Algorithms for Optimization.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:774435110cb8eabb26685e9423591acf7a597ac979a74db8de23f7a35c01edd8
|
| 3 |
+
size 18968167
|
Algorithms for Validation.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:023a4f0d08a1f80db220713a93d463dfd20efb9d193666cc7f5a6d8cb67452cd
|
| 3 |
+
size 13873823
|
Bishop-Pattern-Recognition-and-Machine-Learning.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4ee767e0a6b04fa05ba7e599e9dbb4637a94a4407ccedf0b4d316b1fd7c8ec64
|
| 3 |
+
size 18090775
|
Build-a-large-language-models.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e415ef08f2a2e894d14fe9e665d84e2e889d140c84f8ddf0a6ab897f6f07b9cf
|
| 3 |
+
size 15438848
|
Convex Optimization.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:40d976c83c18cce1900eff8c41bd5ad408c102b813af39d05ff85678ccf8d76e
|
| 3 |
+
size 6881335
|
Deep Learning with Python.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c7af8938d14e1cb7f3344e7e977988ce1c5c3abbae170aa3105313366418e046
|
| 3 |
+
size 14456615
|
Foundations of Machine Learning.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1a986e004028786686d51730693f200429d31424e687c5e18d19e28511852904
|
| 3 |
+
size 6224448
|
Information Theory, Inference, and Learning Algorithms.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:868adc5f0ef6630366b122d88d691acfbe8339978b4ec3f38fca5e231f135791
|
| 3 |
+
size 11675219
|
Introduction to Machine Learning - Nils.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:898374fc2739e35cac27e25eed779d9df2d224da4c6bf66ba2dab5c84c63baa8
|
| 3 |
+
size 1899248
|
Machine-Learning-from-Human-Preferences.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d5440d422504ae86644a88f8f1c0fd1608c315bc868e9220cbc066479f3dff93
|
| 3 |
+
size 1396023
|
Natural Language Processing with Transformers Building Language Applications with Hugging Face by Lewis Tunstall Leandro von Werra Thomas Wolf.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1cf24bd669ccb38c1bcfa67655e852d91a43f78a1c894f9375489366f32e3879
|
| 3 |
+
size 11867230
|
Probabilistic Machine Learning - Advanced Topics.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:54d6bfa8cc4a367bb553bea1c5127ca63696a9655b2ca1f6137a8584dccfdbaf
|
| 3 |
+
size 151421194
|
README.md
ADDED
|
@@ -0,0 +1,962 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
task_categories:
|
| 4 |
+
- text-generation
|
| 5 |
+
- text-classification
|
| 6 |
+
- question-answering
|
| 7 |
+
- summarization
|
| 8 |
+
- sentence-similarity
|
| 9 |
+
- feature-extraction
|
| 10 |
+
- zero-shot-classification
|
| 11 |
+
- text-retrieval
|
| 12 |
+
- token-classification
|
| 13 |
+
- multiple-choice
|
| 14 |
+
- fill-mask
|
| 15 |
+
language:
|
| 16 |
+
- en
|
| 17 |
+
tags:
|
| 18 |
+
- agent
|
| 19 |
+
- ai
|
| 20 |
+
- artificial-intelligence
|
| 21 |
+
- machine-learning
|
| 22 |
+
- ml
|
| 23 |
+
- deep-learning
|
| 24 |
+
- dl
|
| 25 |
+
- neural-networks
|
| 26 |
+
- representation-learning
|
| 27 |
+
- supervised-learning
|
| 28 |
+
- unsupervised-learning
|
| 29 |
+
- semi-supervised-learning
|
| 30 |
+
- self-supervised-learning
|
| 31 |
+
- probabilistic-ml
|
| 32 |
+
- bayesian-learning
|
| 33 |
+
- statistical-learning
|
| 34 |
+
- ml-theory
|
| 35 |
+
- learning-theory
|
| 36 |
+
- generalization
|
| 37 |
+
- optimization
|
| 38 |
+
- convex-optimization
|
| 39 |
+
- gradient-descent
|
| 40 |
+
- stochastic-gradient-descent
|
| 41 |
+
- information-theory
|
| 42 |
+
- entropy
|
| 43 |
+
- kl-divergence
|
| 44 |
+
- causal-inference
|
| 45 |
+
- causality
|
| 46 |
+
- decision-making
|
| 47 |
+
- reinforcement-learning
|
| 48 |
+
- rl
|
| 49 |
+
- multi-agent
|
| 50 |
+
- bandits
|
| 51 |
+
- markov-decision-process
|
| 52 |
+
- transformers
|
| 53 |
+
- attention
|
| 54 |
+
- large-language-models
|
| 55 |
+
- llm
|
| 56 |
+
- foundation-models
|
| 57 |
+
- generative-ai
|
| 58 |
+
- generative-models
|
| 59 |
+
- diffusion-models
|
| 60 |
+
- vae
|
| 61 |
+
- gan
|
| 62 |
+
- autoregressive-models
|
| 63 |
+
- language-modeling
|
| 64 |
+
- nlp
|
| 65 |
+
- natural-language-processing
|
| 66 |
+
- computer-vision
|
| 67 |
+
- multimodal
|
| 68 |
+
- embeddings
|
| 69 |
+
- feature-extraction
|
| 70 |
+
- transfer-learning
|
| 71 |
+
- fine-tuning
|
| 72 |
+
- prompt-engineering
|
| 73 |
+
- rag
|
| 74 |
+
- retrieval-augmented-generation
|
| 75 |
+
- ai-agents
|
| 76 |
+
- ai-engineering
|
| 77 |
+
- ml-engineering
|
| 78 |
+
- model-training
|
| 79 |
+
- model-evaluation
|
| 80 |
+
- validation
|
| 81 |
+
- robustness
|
| 82 |
+
- safety
|
| 83 |
+
- trustworthy-ai
|
| 84 |
+
- explainability
|
| 85 |
+
- interpretability
|
| 86 |
+
- fairness
|
| 87 |
+
- bias
|
| 88 |
+
- responsible-ai
|
| 89 |
+
- datasets
|
| 90 |
+
- dataset
|
| 91 |
+
- benchmark
|
| 92 |
+
- research
|
| 93 |
+
- education
|
| 94 |
+
- textbooks
|
| 95 |
+
- books
|
| 96 |
+
- learning-resources
|
| 97 |
+
- study-guide
|
| 98 |
+
- curriculum
|
| 99 |
+
- knowledge-base
|
| 100 |
+
- open-science
|
| 101 |
+
- pytorch
|
| 102 |
+
- tensorflow
|
| 103 |
+
- huggingface
|
| 104 |
+
- transformers-library
|
| 105 |
+
pretty_name: AI/ML Master Foundations — Curated Research Book Collection
|
| 106 |
+
size_categories:
|
| 107 |
+
- n<1K
|
| 108 |
+
---
|
| 109 |
+
## Introduction
|
| 110 |
+
|
| 111 |
+
I put this collection together after spending a lot of time reading what I think are some of the best books on AI, machine learning, deep learning, probabilistic modeling, optimization, reinforcement learning, transformers, LLMs, validation, and fairness. I want to share this with the community for one simple reason: I want to give people a structured path through the books that actually help them understand things deeply, instead of sending them through random courses, disconnected tutorials, and fragmented content.
|
| 112 |
+
|
| 113 |
+
This collection is my attempt to gather the most important resources I would recommend to anyone who wants to master AI and ML properly: from mathematics and probability, to statistical learning theory, to deep learning, to transformers and LLM engineering, to decision making, robustness, fairness, and causality. There is a reason why these books are on this list. They make up a full ladder that goes from the basics to advanced research-level thinking. They include both theory and practice, both clear math and good engineering judgment, as well as making decisions and predictions.
|
| 114 |
+
|
| 115 |
+
I'm sharing this as a community resource for people who want a real plan. I don't think you should see these books as separate references; instead, I think you should see them as part of a whole curriculum. If someone follows the roadmap below with patience and consistency, they can build a much stronger foundation than what most online courses that are all over the place offer.
|
| 116 |
+
|
| 117 |
+
---
|
| 118 |
+
|
| 119 |
+
## Why this collection exists
|
| 120 |
+
|
| 121 |
+
Most people who enter AI and ML do one of three things:
|
| 122 |
+
|
| 123 |
+
1. They jump straight into model-building without mathematics.
|
| 124 |
+
2. They consume many short courses but never develop deep conceptual structure.
|
| 125 |
+
3. They know pieces of the field but not the full map.
|
| 126 |
+
|
| 127 |
+
I wanted to solve exactly that problem.
|
| 128 |
+
|
| 129 |
+
This collection is for readers who want:
|
| 130 |
+
|
| 131 |
+
* a mathematically grounded path into ML,
|
| 132 |
+
* a principled understanding of probability and inference,
|
| 133 |
+
* real clarity on optimization and generalization,
|
| 134 |
+
* a modern understanding of deep learning and transformers,
|
| 135 |
+
* a path into RL, uncertainty, validation, and causality,
|
| 136 |
+
* and a serious alternative to random fragmented learning.
|
| 137 |
+
|
| 138 |
+
---
|
| 139 |
+
|
| 140 |
+
# Book-by-book explanation
|
| 141 |
+
|
| 142 |
+
## Mathematics for Machine Learning
|
| 143 |
+
|
| 144 |
+
For those who wish to overcome their fear of the math involved in machine learning, I think this is one of the best starting points. It connects the precise mathematical underpinnings—linear algebra, analytic geometry, matrix decompositions, calculus, optimization, probability, and statistics—that are most important for machine learning. Additionally, it establishes a direct connection between those tools and fundamental machine learning techniques like SVMs, PCA, linear regression, and Gaussian mixture models. It is therefore perfect as a "mathematical bridge book" between real machine learning and pure mathematics.
|
| 145 |
+
|
| 146 |
+
## Foundations of Machine Learning
|
| 147 |
+
|
| 148 |
+
One of the collection's important theory books is this one. It advances generalization theory, learnability, complexity, formal guarantees, and the PAC learning framework. In my opinion, it is the book that teaches readers how to rigorously consider what it means for a model to be statistically justified, learn, and generalize. This is a theory-first foundation rather than a practice-first book.
|
| 149 |
+
|
| 150 |
+
## Understanding Machine Learning: From Theory to Algorithms
|
| 151 |
+
|
| 152 |
+
This book is a great addition to *Foundations of Machine Learning*. It focuses on how those principles become algorithms while providing a principled explanation of the concepts underlying learning theory. ERM, convexity, stability, stochastic gradient descent, neural networks, structured output learning, and theoretical concepts such as compression-based bounds and PAC-Bayes are all covered. It is among the best "bridge books" between rigorous theory and algorithmic implementation, in my opinion.
|
| 153 |
+
|
| 154 |
+
## Pattern Recognition and Machine Learning
|
| 155 |
+
|
| 156 |
+
One of the classic books on probabilistic machine learning is this one. Because it develops probabilistic intuition at a very deep level—Bayesian methods, graphical models, approximate inference, latent-variable models, kernel methods, and probabilistic pattern recognition—I have included it. For readers who wish to comprehend machine learning through the lenses of uncertainty, density modeling, and Bayesian reasoning, it continues to be among the best texts.
|
| 157 |
+
|
| 158 |
+
## Machine Learning: A Probabilistic Perspective
|
| 159 |
+
|
| 160 |
+
One of the collection's most extensive and thorough ML books is this one. By combining background math, probability, optimization, linear models, latent-variable models, approximate inference, graphical models, kernel methods, and deep learning into a single probabilistic language, it covers the fundamentals of machine learning. It's among the best "encyclopedic" references for machine learning, in my opinion.
|
| 161 |
+
|
| 162 |
+
## Probabilistic Machine Learning: An Introduction
|
| 163 |
+
|
| 164 |
+
This is how probabilistic machine learning is currently introduced. Probability, multivariate models, statistics, decision theory, information theory, linear algebra, optimization, neural networks, trees, ensembles, clustering, dimensionality reduction, and learning with fewer labels are among the foundational topics covered. It is, in my opinion, one of the greatest contemporary resources for readers seeking a clear and organized probabilistic perspective of the field.
|
| 165 |
+
|
| 166 |
+
## Probabilistic Machine Learning: Advanced Topics
|
| 167 |
+
|
| 168 |
+
One of the most significant books in the entire collection, this is the sophisticated sequel. Advanced inference, Bayesian statistics, graphical models, filtering and smoothing, variational inference, Monte Carlo techniques, Bayesian neural networks, Gaussian processes, distribution shift, generative models, representation learning, interpretability, decision making, reinforcement learning, and causality are all included. This book, in my opinion, marks the beginning of probabilistic machine learning as a comprehensive theory of prediction, generation, discovery, and action.
|
| 169 |
+
|
| 170 |
+
## Information Theory, Inference, and Learning Algorithms
|
| 171 |
+
|
| 172 |
+
This book is special because it sharpens the way we think about entropy, coding, inference, message passing, learning, and compression. It is one of the books that most strongly teaches the unity between information theory and machine learning. Even when it is not directly used in applied pipelines, it changes the way a reader thinks about uncertainty, model selection, and representation.
|
| 173 |
+
|
| 174 |
+
## Convex Optimization
|
| 175 |
+
|
| 176 |
+
This is the canonical reference for convex sets, convex functions, duality, KKT conditions, and optimization theory. I include it because optimization is not just a tool in ML; it is one of the structural cores of the field. Readers who understand this book well gain a much deeper command over learning objectives, constrained optimization, regularization, dual methods, and algorithmic guarantees.
|
| 177 |
+
|
| 178 |
+
## Algorithms for Optimization
|
| 179 |
+
|
| 180 |
+
This book complements *Convex Optimization* by being more algorithm-focused and method-oriented. It covers gradients, bracketing, local descent, first-order methods, second-order methods, stochastic methods, population methods, constrained optimization, duality, LP, QP, and ADMM. I see it as one of the most useful optimization books for practitioners who want algorithmic understanding instead of only theory.
|
| 181 |
+
|
| 182 |
+
## Deep Learning with Python
|
| 183 |
+
|
| 184 |
+
This is a practical and highly accessible deep learning book. It introduces neural networks, Keras, TensorFlow workflows, computer vision, text, timeseries, generative modeling, and real-world deep learning practices. I include it because it helps readers move from mathematical foundations into real neural network intuition and implementation.
|
| 185 |
+
|
| 186 |
+
## Understanding Deep Learning
|
| 187 |
+
|
| 188 |
+
This is one of the clearest modern books on deep learning fundamentals. It explains supervised learning, neural networks, deep architectures, loss functions, fitting models, gradient descent, stochastic optimization, initialization, and modern deep learning concepts with unusual clarity. I consider it one of the best deep learning books for readers who want concept-first understanding without sacrificing mathematical structure.
|
| 189 |
+
|
| 190 |
+
## The Principles of Deep Learning Theory
|
| 191 |
+
|
| 192 |
+
This is a research-oriented theory book focused on initialization, criticality, Gaussian-process limits, finite- and infinite-width analysis, Bayesian inference in neural networks, and the effective theory viewpoint. I include it because it pushes readers beyond practical deep learning into the theory frontier. It is not the first DL book to read, but it is one of the most valuable advanced theory books.
|
| 193 |
+
|
| 194 |
+
## Natural Language Processing with Transformers
|
| 195 |
+
|
| 196 |
+
This book is one of the strongest practical guides to modern NLP and transformer-based systems. It covers pretrained transformers, Hugging Face workflows, multilingual models, question answering, generation, fine-tuning, deployment, and practical engineering considerations. I consider it essential for moving from general deep learning into modern NLP and transformer applications.
|
| 197 |
+
|
| 198 |
+
## Build a Large Language Model (From Scratch)
|
| 199 |
+
|
| 200 |
+
This book is valuable because it teaches LLMs by construction. It walks through data preparation, attention, architecture, pretraining, evaluation, loading pretrained weights, and fine-tuning for classifiers and assistants. I include it because building an LLM from scratch is one of the best ways to deeply understand what an LLM really is.
|
| 201 |
+
|
| 202 |
+
## AI Engineering Guidebook
|
| 203 |
+
|
| 204 |
+
This book focuses on system design patterns for LLMs, RAG, agents, prompt engineering, fine-tuning, and deployment-oriented engineering. I include it because knowing models is not enough; real AI work today also requires understanding inference pipelines, retrieval, orchestration, local deployment, and product architecture.
|
| 205 |
+
|
| 206 |
+
## Reinforcement Learning: An Introduction
|
| 207 |
+
|
| 208 |
+
This is the foundational RL book. It covers bandits, Markov decision processes, value functions, dynamic programming, Monte Carlo methods, temporal-difference learning, policy gradients, and more. I recommend it as the first serious RL book in the roadmap.
|
| 209 |
+
|
| 210 |
+
## Algorithms for Decision Making
|
| 211 |
+
|
| 212 |
+
This book connects probabilistic reasoning, inference, utility, MDPs, planning, policy search, policy gradients, actor-critic methods, and policy validation. I see it as a beautiful bridge between probability, planning, and reinforcement learning.
|
| 213 |
+
|
| 214 |
+
## Multi-Agent Reinforcement Learning
|
| 215 |
+
|
| 216 |
+
This is the modern extension into multi-agent systems and MARL. It combines game-theoretic foundations with contemporary learning methods. I recommend it only after strong single-agent RL understanding, because it adds strategic interaction, coordination, and game structure on top of standard RL ideas.
|
| 217 |
+
|
| 218 |
+
## Algorithms for Validation
|
| 219 |
+
|
| 220 |
+
This is one of the most important books for trustworthy AI and safety-oriented ML. It covers validation, system modeling, property specification, falsification, reachability, failure estimation, explainability, and runtime monitoring. I include it because average benchmark performance is not enough for serious AI systems.
|
| 221 |
+
|
| 222 |
+
## Fairness and Machine Learning
|
| 223 |
+
|
| 224 |
+
This book addresses fairness, legitimacy of automated decision making, classification, non-discrimination criteria, and the sociotechnical limits of purely observational fairness frameworks. I include it because real-world ML needs both mathematical and institutional responsibility.
|
| 225 |
+
|
| 226 |
+
---
|
| 227 |
+
|
| 228 |
+
# Recommended roadmap
|
| 229 |
+
|
| 230 |
+
## Level 0: Mathematics and optimization foundation
|
| 231 |
+
|
| 232 |
+
I recommend starting here if the reader wants to build from first principles:
|
| 233 |
+
|
| 234 |
+
1. **Mathematics for Machine Learning**
|
| 235 |
+
2. **Convex Optimization**
|
| 236 |
+
3. **Algorithms for Optimization**
|
| 237 |
+
|
| 238 |
+
This stage builds the language of vectors, matrices, eigendecompositions, gradients, Hessians, constraints, and optimization geometry. Without this stage, later ML understanding often becomes shallow.
|
| 239 |
+
|
| 240 |
+
## Level 1: Core machine learning foundation
|
| 241 |
+
|
| 242 |
+
After math, I recommend:
|
| 243 |
+
|
| 244 |
+
1. **Probabilistic Machine Learning: An Introduction**
|
| 245 |
+
2. **Understanding Machine Learning**
|
| 246 |
+
3. **Foundations of Machine Learning**
|
| 247 |
+
|
| 248 |
+
This stage gives the reader the foundations of probability, learning theory, empirical risk minimization, statistical thinking, and formal generalization.
|
| 249 |
+
|
| 250 |
+
## Level 2: Probabilistic depth
|
| 251 |
+
|
| 252 |
+
Then I recommend:
|
| 253 |
+
|
| 254 |
+
1. **Pattern Recognition and Machine Learning**
|
| 255 |
+
2. **Machine Learning: A Probabilistic Perspective**
|
| 256 |
+
3. **Probabilistic Machine Learning: Advanced Topics**
|
| 257 |
+
4. **Information Theory, Inference, and Learning Algorithms**
|
| 258 |
+
|
| 259 |
+
This stage builds a complete mature probabilistic worldview. Here the reader learns to think in terms of posterior inference, latent variables, uncertainty, graphical structure, divergence measures, and information flow.
|
| 260 |
+
|
| 261 |
+
## Level 3: Deep learning
|
| 262 |
+
|
| 263 |
+
Then I recommend:
|
| 264 |
+
|
| 265 |
+
1. **Deep Learning with Python**
|
| 266 |
+
2. **Understanding Deep Learning**
|
| 267 |
+
3. **The Principles of Deep Learning Theory**
|
| 268 |
+
|
| 269 |
+
This stage moves from practice to conceptual depth to research theory. Readers first build intuition, then clean understanding, then more advanced theoretical maturity.
|
| 270 |
+
|
| 271 |
+
## Level 4: NLP, transformers, and LLMs
|
| 272 |
+
|
| 273 |
+
Then:
|
| 274 |
+
|
| 275 |
+
1. **Natural Language Processing with Transformers**
|
| 276 |
+
2. **Build a Large Language Model (From Scratch)**
|
| 277 |
+
3. **AI Engineering Guidebook**
|
| 278 |
+
|
| 279 |
+
This stage turns deep learning understanding into transformer fluency and finally into LLM systems engineering.
|
| 280 |
+
|
| 281 |
+
## Level 5: Decision making and RL
|
| 282 |
+
|
| 283 |
+
Then:
|
| 284 |
+
|
| 285 |
+
1. **Reinforcement Learning: An Introduction**
|
| 286 |
+
2. **Algorithms for Decision Making**
|
| 287 |
+
3. **Multi-Agent Reinforcement Learning**
|
| 288 |
+
|
| 289 |
+
This stage extends the reader from prediction into sequential decision making, planning, policy optimization, and strategic multi-agent interaction.
|
| 290 |
+
|
| 291 |
+
## Level 6: Trustworthy and societally grounded AI
|
| 292 |
+
|
| 293 |
+
Finally:
|
| 294 |
+
|
| 295 |
+
1. **Algorithms for Validation**
|
| 296 |
+
2. **Fairness and Machine Learning**
|
| 297 |
+
|
| 298 |
+
This stage matters because building a model is not the same as building a safe, robust, interpretable, or fair system.
|
| 299 |
+
|
| 300 |
+
---
|
| 301 |
+
|
| 302 |
+
# My master notes and main concept understanding after I read those books
|
| 303 |
+
|
| 304 |
+
Below I am not trying to rewrite the books in full. I am only extracting the most important concepts and master formulas that I believe form the deep structure across the whole collection as master notes.
|
| 305 |
+
|
| 306 |
+
---
|
| 307 |
+
|
| 308 |
+
## 1. Learning as optimization
|
| 309 |
+
|
| 310 |
+
A very large fraction of ML can be written as:
|
| 311 |
+
|
| 312 |
+
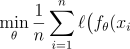,y_i\big)+\lambda\Omega(\theta))
|
| 313 |
+
|
| 314 |
+
where:
|
| 315 |
+
|
| 316 |
+
*  is the model,
|
| 317 |
+
*  is the loss function,
|
| 318 |
+
*  is a regularizer,
|
| 319 |
+
*  controls complexity.
|
| 320 |
+
|
| 321 |
+
Linear models, logistic regression, neural networks, transformers, numerous probabilistic models, and even portions of reinforcement learning through surrogate objectives are all combined into one template.
|
| 322 |
+
|
| 323 |
+
The idea is that machine learning is more than just "fitting data." It involves **optimizing a tradeoff** between managing model complexity and fitting the observed data.
|
| 324 |
+
|
| 325 |
+
---
|
| 326 |
+
|
| 327 |
+
## 2. Empirical risk, expected risk, and generalization
|
| 328 |
+
|
| 329 |
+
The true objective is not training performance but expected performance on the underlying data distribution:
|
| 330 |
+
|
| 331 |
+
=\mathbb{E}_{(x,y)\sim\mathcal{D}}%5B\ell(f(x),y)%5D)
|
| 332 |
+
|
| 333 |
+
Since  is unknown, we instead minimize empirical risk:
|
| 334 |
+
|
| 335 |
+
=\frac{1}{n}\sum_{i=1}^{n}\ell(f(x_i),y_i))
|
| 336 |
+
|
| 337 |
+
and perform ERM:
|
| 338 |
+
|
| 339 |
+
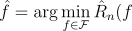)
|
| 340 |
+
|
| 341 |
+
The central question of learning theory is then:
|
| 342 |
+
|
| 343 |
+
\text{%20to%20}R(f)?)
|
| 344 |
+
|
| 345 |
+
PAC learning, VC dimension, stability, margins, and Rademacher complexity all become significant at this point. The field is about **justified generalization** rather than merely fitting.
|
| 346 |
+
|
| 347 |
+
---
|
| 348 |
+
|
| 349 |
+
## 3. Probability as the language of uncertainty
|
| 350 |
+
|
| 351 |
+
Probability is the language that ties together Bayesian reasoning, inference, decision theory, graphical models, latent-variable models, generative modeling, and uncertainty-aware prediction.
|
| 352 |
+
|
| 353 |
+
Basic probability identities:
|
| 354 |
+
|
| 355 |
+
=\frac{P(B\mid%20A)P(A)}{P(B)})
|
| 356 |
+
|
| 357 |
+
=\sum_zP(x,z)\quad\text{or}\quad%20p(x)=\int%20p(x,z)\,dz)
|
| 358 |
+
|
| 359 |
+
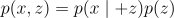
|
| 360 |
+
|
| 361 |
+
The most important conceptual objects are:
|
| 362 |
+
|
| 363 |
+
* **prior**: 
|
| 364 |
+
* **likelihood**: 
|
| 365 |
+
* **posterior**: 
|
| 366 |
+
* **evidence / marginal likelihood**: 
|
| 367 |
+
|
| 368 |
+
Bayesian updating then becomes:
|
| 369 |
+
|
| 370 |
+
=\frac{p(x\mid%20z)p(z)}{p(x)})
|
| 371 |
+
|
| 372 |
+
This pattern appears across PRML, Murphy's books, MacKay, graphical models, Bayesian neural networks, filtering, and causal inference.
|
| 373 |
+
|
| 374 |
+
---
|
| 375 |
+
|
| 376 |
+
## 4. Likelihood, MLE, and MAP
|
| 377 |
+
|
| 378 |
+
Given data \}_{i=1}^{n}), the likelihood is:
|
| 379 |
+
|
| 380 |
+
=p(D\mid\theta)=\prod_{i=1}^{n}p(y_i\mid%20x_i,\theta))
|
| 381 |
+
|
| 382 |
+
Taking logs:
|
| 383 |
+
|
| 384 |
+
=\sum_{i=1}^{n}\log%20p(y_i\mid%20x_i,\theta))
|
| 385 |
+
|
| 386 |
+
Maximum likelihood estimation is:
|
| 387 |
+
|
| 388 |
+
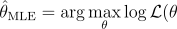)
|
| 389 |
+
|
| 390 |
+
Maximum a posteriori estimation adds a prior:
|
| 391 |
+
|
| 392 |
+
+\log%20p(\theta)\right%5D)
|
| 393 |
+
|
| 394 |
+
Equivalently:
|
| 395 |
+
|
| 396 |
+
-\log%20p(\theta)\right%5D)
|
| 397 |
+
|
| 398 |
+
This is the deep bridge between Bayesian reasoning and regularization:
|
| 399 |
+
|
| 400 |
+
* Gaussian prior  regularization
|
| 401 |
+
* Laplace prior  regularization
|
| 402 |
+
|
| 403 |
+
---
|
| 404 |
+
|
| 405 |
+
## 5. Linear regression as the prototype
|
| 406 |
+
|
| 407 |
+
The simplest but most important predictive model is:
|
| 408 |
+
|
| 409 |
+
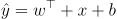
|
| 410 |
+
|
| 411 |
+
with squared loss:
|
| 412 |
+
|
| 413 |
+
=\frac{1}{n}\sum_{i=1}^{n}(y_i-w^\top%20x_i-b)^2)
|
| 414 |
+
|
| 415 |
+
Closed-form solution:
|
| 416 |
+
|
| 417 |
+
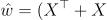^{-1}X^\top%20y)
|
| 418 |
+
|
| 419 |
+
Ridge regression:
|
| 420 |
+
|
| 421 |
+
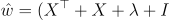^{-1}X^\top%20y)
|
| 422 |
+
|
| 423 |
+
This model matters because it teaches many of the core ideas of the entire field in a clean setting:
|
| 424 |
+
|
| 425 |
+
* projection geometry,
|
| 426 |
+
* Gaussian-noise interpretation,
|
| 427 |
+
* bias-variance tradeoff,
|
| 428 |
+
* regularization,
|
| 429 |
+
* conditioning and numerical stability,
|
| 430 |
+
* Bayesian linear modeling.
|
| 431 |
+
|
| 432 |
+
---
|
| 433 |
+
|
| 434 |
+
## 6. Logistic regression and classification
|
| 435 |
+
|
| 436 |
+
Binary logistic regression models class probabilities using the sigmoid:
|
| 437 |
+
|
| 438 |
+
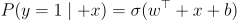
|
| 439 |
+
|
| 440 |
+
=\frac{1}{1+e^{-z}})
|
| 441 |
+
|
| 442 |
+
The negative log-likelihood is the binary cross-entropy loss:
|
| 443 |
+
|
| 444 |
+
=-\sum_{i=1}^{n}\left%5By_i\log\hat{p}_i+(1-y_i)\log(1-\hat{p}_i)\right%5D)
|
| 445 |
+
|
| 446 |
+
Multiclass logistic regression uses softmax:
|
| 447 |
+
|
| 448 |
+
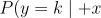=\frac{e^{z_k}}{\sum_je^{z_j}})
|
| 449 |
+
|
| 450 |
+
with loss:
|
| 451 |
+
|
| 452 |
+
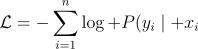)
|
| 453 |
+
|
| 454 |
+
This is one of the most important bridges in all of ML because it connects probability, classification, linear models, gradient-based optimization, and neural network output layers.
|
| 455 |
+
|
| 456 |
+
---
|
| 457 |
+
|
| 458 |
+
## 7. The exponential family
|
| 459 |
+
|
| 460 |
+
Many widely used distributions can be written as:
|
| 461 |
+
|
| 462 |
+
=h(x)\exp\big(\eta^\top%20T(x)-A(\eta)\big))
|
| 463 |
+
|
| 464 |
+
where:
|
| 465 |
+
|
| 466 |
+
*  are sufficient statistics,
|
| 467 |
+
*  are natural parameters,
|
| 468 |
+
*  is the log-partition function.
|
| 469 |
+
|
| 470 |
+
This family matters because it unifies Bernoulli, Gaussian, Poisson, categorical, and many more. It also lies underneath GLMs, conjugacy, variational inference, message passing, and natural gradients.
|
| 471 |
+
|
| 472 |
+
---
|
| 473 |
+
|
| 474 |
+
## 8. Information theory as a master layer
|
| 475 |
+
|
| 476 |
+
Entropy:
|
| 477 |
+
|
| 478 |
+
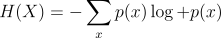
|
| 479 |
+
|
| 480 |
+
Cross-entropy:
|
| 481 |
+
|
| 482 |
+
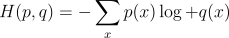
|
| 483 |
+
|
| 484 |
+
KL divergence:
|
| 485 |
+
|
| 486 |
+
=\sum_xp(x)\log\frac{p(x)}{q(x)})
|
| 487 |
+
|
| 488 |
+
Mutual information:
|
| 489 |
+
|
| 490 |
+
=\sum_{x,y}p(x,y)\log\frac{p(x,y)}{p(x)p(y)})
|
| 491 |
+
|
| 492 |
+
These ideas are not peripheral. They are central across the books:
|
| 493 |
+
|
| 494 |
+
* cross-entropy is the standard classification loss,
|
| 495 |
+
* KL is central in VI, distillation, and approximate Bayes,
|
| 496 |
+
* entropy measures uncertainty and exploration,
|
| 497 |
+
* mutual information appears in representation learning and bottleneck methods,
|
| 498 |
+
* coding and compression ideas connect learning to information structure.
|
| 499 |
+
|
| 500 |
+
---
|
| 501 |
+
|
| 502 |
+
## 9. Bias–variance tradeoff
|
| 503 |
+
|
| 504 |
+
In a simplified regression view:
|
| 505 |
+
|
| 506 |
+
)^2\big%5D=\text{Bias}^2+\text{Variance}+\text{Noise})
|
| 507 |
+
|
| 508 |
+
This gives one of the most important conceptual lessons in ML:
|
| 509 |
+
|
| 510 |
+
* small models underfit because of high bias,
|
| 511 |
+
* very flexible models can overfit because of high variance,
|
| 512 |
+
* regularization and inductive bias control the tradeoff.
|
| 513 |
+
|
| 514 |
+
This pattern reappears in linear models, trees, kernels, ensembles, and deep neural networks.
|
| 515 |
+
|
| 516 |
+
---
|
| 517 |
+
|
| 518 |
+
## 10. Convexity and optimization geometry
|
| 519 |
+
|
| 520 |
+
A differentiable function is convex if:
|
| 521 |
+
|
| 522 |
+
y)\leq\theta%20f(x)+(1-\theta)f(y)\quad\forall\theta\in%5B0,1%5D)
|
| 523 |
+
|
| 524 |
+
For convex differentiable functions:
|
| 525 |
+
|
| 526 |
+

|
| 527 |
+
|
| 528 |
+
Convexity matters because local minima are global minima, optimization is more stable, and duality becomes powerful.
|
| 529 |
+
|
| 530 |
+
For constrained optimization:
|
| 531 |
+
|
| 532 |
+
\quad\text{s.t.%20}g_i(x)\leq0,\;h_j(x)=0)
|
| 533 |
+
|
| 534 |
+
the Lagrangian is:
|
| 535 |
+
|
| 536 |
+
=f(x)+\sum_i\lambda_ig_i(x)+\sum_j\nu_jh_j(x))
|
| 537 |
+
|
| 538 |
+
and KKT conditions become fundamental:
|
| 539 |
+
|
| 540 |
+
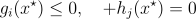
|
| 541 |
+
|
| 542 |
+

|
| 543 |
+
|
| 544 |
+
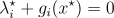
|
| 545 |
+
|
| 546 |
+
=0)
|
| 547 |
+
|
| 548 |
+
These ideas sit underneath SVMs, constrained estimation, dual optimization, and many optimization-based ML methods.
|
| 549 |
+
|
| 550 |
+
---
|
| 551 |
+
|
| 552 |
+
## 11. Gradient descent, SGD, momentum, and Adam
|
| 553 |
+
|
| 554 |
+
Standard gradient descent:
|
| 555 |
+
|
| 556 |
+
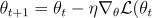)
|
| 557 |
+
|
| 558 |
+
Mini-batch stochastic gradient descent:
|
| 559 |
+
|
| 560 |
+
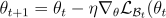)
|
| 561 |
+
|
| 562 |
+
Momentum:
|
| 563 |
+
|
| 564 |
+
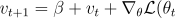,\qquad\theta_{t+1}=\theta_t-\eta%20v_{t+1})
|
| 565 |
+
|
| 566 |
+
Adam:
|
| 567 |
+
|
| 568 |
+
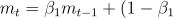g_t)
|
| 569 |
+
|
| 570 |
+
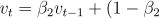g_t^2)
|
| 571 |
+
|
| 572 |
+
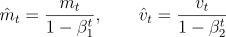
|
| 573 |
+
|
| 574 |
+
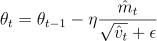
|
| 575 |
+
|
| 576 |
+
These are the workhorse update rules behind modern deep learning and a large fraction of practical ML.
|
| 577 |
+
|
| 578 |
+
---
|
| 579 |
+
|
| 580 |
+
## 12. Neural networks as compositional function approximators
|
| 581 |
+
|
| 582 |
+
A feedforward neural network composes affine maps and nonlinearities:
|
| 583 |
+
|
| 584 |
+
}=\phi(W^{(1)}x+b^{(1)}))
|
| 585 |
+
|
| 586 |
+
}=\phi(W^{(l)}h^{(l-1)}+b^{(l)}))
|
| 587 |
+
|
| 588 |
+
}h^{(L-1)}+b^{(L)})
|
| 589 |
+
|
| 590 |
+
The real power of deep learning is not just "many parameters." It is **hierarchical representation learning** through compositional structure.
|
| 591 |
+
|
| 592 |
+
Backpropagation is the chain rule applied efficiently across this composition:
|
| 593 |
+
|
| 594 |
+
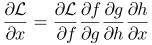
|
| 595 |
+
|
| 596 |
+
For a dense layer , :
|
| 597 |
+
|
| 598 |
+
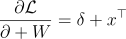
|
| 599 |
+
|
| 600 |
+
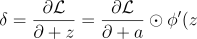)
|
| 601 |
+
|
| 602 |
+
---
|
| 603 |
+
|
| 604 |
+
## 13. Initialization and trainability
|
| 605 |
+
|
| 606 |
+
Deep networks are sensitive to activation and gradient scales. Good initialization helps preserve signal and gradient flow.
|
| 607 |
+
|
| 608 |
+
Xavier / Glorot initialization:
|
| 609 |
+
|
| 610 |
+
\approx\frac{2}{n_{\text{in}}+n_{\text{out}}})
|
| 611 |
+
|
| 612 |
+
He initialization:
|
| 613 |
+
|
| 614 |
+
\approx\frac{2}{n_{\text{in}}})
|
| 615 |
+
|
| 616 |
+
This matters because training failure often comes not from the optimizer alone, but from bad signal propagation through depth. That is one reason the theory books on deep learning pay so much attention to initialization, criticality, and scaling.
|
| 617 |
+
|
| 618 |
+
---
|
| 619 |
+
|
| 620 |
+
## 14. Variational inference and the ELBO
|
| 621 |
+
|
| 622 |
+
When exact posterior inference is intractable, variational inference approximates it with a tractable family .
|
| 623 |
+
|
| 624 |
+
The key identity is:
|
| 625 |
+
|
| 626 |
+
=\mathcal{L}(q)+D_{\mathrm{KL}}\big(q(z)%7Cp(z\mid%20x)\big))
|
| 627 |
+
|
| 628 |
+
where the evidence lower bound is:
|
| 629 |
+
|
| 630 |
+
=\mathbb{E}_{q(z)}%5B\log%20p(x,z)-\log%20q(z)%5D)
|
| 631 |
+
|
| 632 |
+
Equivalently:
|
| 633 |
+
|
| 634 |
+
=\mathbb{E}_{q(z)}%5B\log%20p(x\mid%20z)%5D-D_{\mathrm{KL}}(q(z)%7Cp(z)))
|
| 635 |
+
|
| 636 |
+
Since KL is nonnegative, maximizing the ELBO makes  closer to the true posterior.
|
| 637 |
+
|
| 638 |
+
This one framework powers:
|
| 639 |
+
|
| 640 |
+
* latent-variable models,
|
| 641 |
+
* VAEs,
|
| 642 |
+
* amortized inference,
|
| 643 |
+
* Bayesian deep learning,
|
| 644 |
+
* large-scale approximate Bayesian methods.
|
| 645 |
+
|
| 646 |
+
---
|
| 647 |
+
|
| 648 |
+
## 15. Gaussian processes and function-space thinking
|
| 649 |
+
|
| 650 |
+
A Gaussian process defines a distribution over functions:
|
| 651 |
+
|
| 652 |
+
,k(x,x')))
|
| 653 |
+
|
| 654 |
+
where  is the mean function and  is the kernel.
|
| 655 |
+
|
| 656 |
+
The conceptual leap here is powerful: instead of putting uncertainty over parameters, I can put uncertainty directly over functions.
|
| 657 |
+
|
| 658 |
+
Gaussian processes matter because they teach:
|
| 659 |
+
|
| 660 |
+
* uncertainty-aware prediction,
|
| 661 |
+
* the role of kernels,
|
| 662 |
+
* Bayesian function-space inference,
|
| 663 |
+
* the relationship between infinite-width networks and kernel limits.
|
| 664 |
+
|
| 665 |
+
---
|
| 666 |
+
|
| 667 |
+
## 16. Bayesian neural networks and predictive uncertainty
|
| 668 |
+
|
| 669 |
+
In Bayesian neural networks, I put a posterior over parameters:
|
| 670 |
+
|
| 671 |
+
)
|
| 672 |
+
|
| 673 |
+
and then predictive uncertainty becomes:
|
| 674 |
+
|
| 675 |
+
=\int%20p(y_\ast\mid%20x_\ast,\theta)\,p(\theta\mid\mathcal{D})\,d\theta)
|
| 676 |
+
|
| 677 |
+
This is one of the cleanest ways to represent epistemic uncertainty in neural prediction. Approximation strategies include VI, Laplace approximations, MCMC, dropout-based approximations, and deep ensembles.
|
| 678 |
+
|
| 679 |
+
---
|
| 680 |
+
|
| 681 |
+
## 17. Attention and transformers
|
| 682 |
+
|
| 683 |
+
The core transformer mechanism is scaled dot-product attention:
|
| 684 |
+
|
| 685 |
+
=\mathrm{softmax}\!\left(\frac{QK^\top}{\sqrt{d_k}}\right)V)
|
| 686 |
+
|
| 687 |
+
Self-attention uses:
|
| 688 |
+
|
| 689 |
+
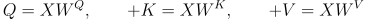
|
| 690 |
+
|
| 691 |
+
Multi-head attention computes several attention maps in parallel:
|
| 692 |
+
|
| 693 |
+
=\mathrm{Concat}(\text{head}_1,\dots,\text{head}_H)W^O)
|
| 694 |
+
|
| 695 |
+
The key conceptual lesson is that attention lets a model dynamically route information based on relevance rather than fixed local structure. This is one reason transformers generalized so strongly across text, vision, and multimodal systems.
|
| 696 |
+
|
| 697 |
+
---
|
| 698 |
+
|
| 699 |
+
## 18. Language modeling and LLMs
|
| 700 |
+
|
| 701 |
+
Autoregressive language modeling factors a sequence as:
|
| 702 |
+
|
| 703 |
+
=\prod_{t=1}^{T}P(x_t\mid%20x_{%3Ct}))
|
| 704 |
+
|
| 705 |
+
Training objective:
|
| 706 |
+
|
| 707 |
+
)
|
| 708 |
+
|
| 709 |
+
Perplexity:
|
| 710 |
+
|
| 711 |
+
\right))
|
| 712 |
+
|
| 713 |
+
This is the master probabilistic formulation behind GPT-style pretraining. LLMs are best understood as large autoregressive probabilistic sequence models trained at scale.
|
| 714 |
+
|
| 715 |
+
---
|
| 716 |
+
|
| 717 |
+
## 19. Fine-tuning and distillation
|
| 718 |
+
|
| 719 |
+
Supervised fine-tuning objective:
|
| 720 |
+
|
| 721 |
+
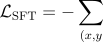}\log%20P_\theta(y\mid%20x))
|
| 722 |
+
|
| 723 |
+
Knowledge distillation:
|
| 724 |
+
|
| 725 |
+
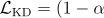\mathcal{L}_{\text{hard}}+\alpha%20T^2%20D_{\mathrm{KL}}\!\left(p_T^{\text{teacher}}%7C%7Cp_T^{\text{student}}\right))
|
| 726 |
+
|
| 727 |
+
The conceptual point is that a student model can learn not only ground-truth labels but also the teacher's richer soft distribution over outputs.
|
| 728 |
+
|
| 729 |
+
---
|
| 730 |
+
|
| 731 |
+
## 20. Retrieval-augmented generation and AI engineering
|
| 732 |
+
|
| 733 |
+
In a simplified RAG pipeline:
|
| 734 |
+
|
| 735 |
+
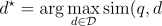)
|
| 736 |
+
|
| 737 |
+

|
| 738 |
+
|
| 739 |
+
This shows the core architecture idea:
|
| 740 |
+
|
| 741 |
+
* model weights contain **parametric memory**,
|
| 742 |
+
* the retriever/index provides **nonparametric memory**.
|
| 743 |
+
|
| 744 |
+
Modern LLM systems often perform best when both are combined. That is why AI engineering is not just about model size or fine-tuning, but also about retrieval, orchestration, evaluation, and system design.
|
| 745 |
+
|
| 746 |
+
---
|
| 747 |
+
|
| 748 |
+
## 21. Markov decision processes and RL
|
| 749 |
+
|
| 750 |
+
A Markov decision process is:
|
| 751 |
+
|
| 752 |
+
)
|
| 753 |
+
|
| 754 |
+
Return:
|
| 755 |
+
|
| 756 |
+
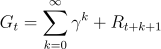
|
| 757 |
+
|
| 758 |
+
State-value function:
|
| 759 |
+
|
| 760 |
+
=\mathbb{E}_\pi%5BG_t\mid%20S_t=s%5D)
|
| 761 |
+
|
| 762 |
+
Action-value function:
|
| 763 |
+
|
| 764 |
+
=\mathbb{E}_\pi%5BG_t\mid%20S_t=s,A_t=a%5D)
|
| 765 |
+
|
| 766 |
+
Bellman expectation equation:
|
| 767 |
+
|
| 768 |
+
=\sum_a\pi(a\mid%20s)\sum_{s',r}p(s',r\mid%20s,a)\big%5Br+\gamma%20V^\pi(s')\big%5D)
|
| 769 |
+
|
| 770 |
+
Bellman optimality equation:
|
| 771 |
+
|
| 772 |
+
=\max_a\sum_{s',r}p(s',r\mid%20s,a)\big%5Br+\gamma%20V^\star(s')\big%5D)
|
| 773 |
+
|
| 774 |
+
These equations form the mathematical backbone of RL and sequential decision making.
|
| 775 |
+
|
| 776 |
+
---
|
| 777 |
+
|
| 778 |
+
## 22. Temporal-difference learning and policy gradients
|
| 779 |
+
|
| 780 |
+
TD value update:
|
| 781 |
+
|
| 782 |
+
\leftarrow%20V(S_t)+\alpha\Big(R_{t+1}+\gamma%20V(S_{t+1})-V(S_t)\Big))
|
| 783 |
+
|
| 784 |
+
Q-learning:
|
| 785 |
+
|
| 786 |
+
\leftarrow%20Q(S_t,A_t)+\alpha\Big(R_{t+1}+\gamma\max_aQ(S_{t+1},a)-Q(S_t,A_t)\Big))
|
| 787 |
+
|
| 788 |
+
Policy gradient objective:
|
| 789 |
+
|
| 790 |
+
=\mathbb{E}_{\tau\sim\pi_\theta}%5BR(\tau)%5D)
|
| 791 |
+
|
| 792 |
+
REINFORCE gradient:
|
| 793 |
+
|
| 794 |
+
=\mathbb{E}\!\left%5B\sum_t\nabla_\theta\log\pi_\theta(a_t\mid%20s_t)\,G_t\right%5D)
|
| 795 |
+
|
| 796 |
+
These formulas explain the main split in RL:
|
| 797 |
+
|
| 798 |
+
* value-based learning,
|
| 799 |
+
* policy-based learning,
|
| 800 |
+
* actor-critic hybrids.
|
| 801 |
+
|
| 802 |
+
---
|
| 803 |
+
|
| 804 |
+
## 23. Exploration vs exploitation
|
| 805 |
+
|
| 806 |
+
In bandits and RL, the system must balance using what it knows and discovering what it does not know.
|
| 807 |
+
|
| 808 |
+
One canonical exploration rule is UCB:
|
| 809 |
+
|
| 810 |
+
+c\sqrt{\frac{\ln%20t}{N_t(a)}}\right%5D)
|
| 811 |
+
|
| 812 |
+
This captures a deep principle: act according to both current value estimate and uncertainty bonus.
|
| 813 |
+
|
| 814 |
+
Another key idea is Thompson sampling: sample from the posterior and act optimally under the sample. This naturally links Bayesian uncertainty to exploration.
|
| 815 |
+
|
| 816 |
+
---
|
| 817 |
+
|
| 818 |
+
## 24. Decision theory
|
| 819 |
+
|
| 820 |
+
Prediction is not enough; action depends on utility.
|
| 821 |
+
|
| 822 |
+
Expected utility principle:
|
| 823 |
+
|
| 824 |
+
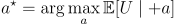
|
| 825 |
+
|
| 826 |
+
or equivalently with losses:
|
| 827 |
+
|
| 828 |
+
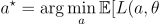\mid%20x%5D)
|
| 829 |
+
|
| 830 |
+
This is one of the deepest ideas in the collection. Many practical systems fail because they optimize prediction accuracy without explicitly reasoning about utility, cost, risk, and downstream decisions.
|
| 831 |
+
|
| 832 |
+
---
|
| 833 |
+
|
| 834 |
+
## 25. Distribution shift and robustness
|
| 835 |
+
|
| 836 |
+
One of the most important advanced lessons in modern ML is that train and test distributions often differ.
|
| 837 |
+
|
| 838 |
+
Under covariate shift:
|
| 839 |
+
|
| 840 |
+
=\mathbb{E}_{(x,y)\sim%20p_{\text{test}}}%5B\ell(f(x),y)%5D=\mathbb{E}_{(x,y)\sim%20p_{\text{train}}}\!\left%5B\frac{p_{\text{test}}(x)}{p_{\text{train}}(x)}\ell(f(x),y)\right%5D)
|
| 841 |
+
|
| 842 |
+
This leads to reweighting strategies, adaptation, and robust training ideas.
|
| 843 |
+
|
| 844 |
+
Modern ML needs to account for:
|
| 845 |
+
|
| 846 |
+
* covariate shift,
|
| 847 |
+
* label shift,
|
| 848 |
+
* domain adaptation,
|
| 849 |
+
* continual learning,
|
| 850 |
+
* OOD detection,
|
| 851 |
+
* adversarial examples.
|
| 852 |
+
|
| 853 |
+
---
|
| 854 |
+
|
| 855 |
+
## 26. Generative modeling taxonomy
|
| 856 |
+
|
| 857 |
+
Modern generative AI can be seen through several major families:
|
| 858 |
+
|
| 859 |
+
### Variational autoencoders
|
| 860 |
+
|
| 861 |
+
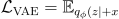}%5B\log%20p_\theta(x\mid%20z)%5D-D_{\mathrm{KL}}(q_\phi(z\mid%20x)%7Cp(z)))
|
| 862 |
+
|
| 863 |
+
### Autoregressive models
|
| 864 |
+
|
| 865 |
+
=\prod_{t=1}^{T}p(x_t\mid%20x_{%3Ct}))
|
| 866 |
+
|
| 867 |
+
### Normalizing flows
|
| 868 |
+
|
| 869 |
+
=p_Z(f(x))\left|\det\frac{\partial%20f(x)}{\partial%20x}\right|)
|
| 870 |
+
|
| 871 |
+
### Diffusion models
|
| 872 |
+
|
| 873 |
+
Forward corruption:
|
| 874 |
+
|
| 875 |
+
)
|
| 876 |
+
|
| 877 |
+
Learned reverse denoising:
|
| 878 |
+
|
| 879 |
+
)
|
| 880 |
+
|
| 881 |
+
### GANs
|
| 882 |
+
|
| 883 |
+
A generator and discriminator are trained in opposition through adversarial objectives.
|
| 884 |
+
|
| 885 |
+
The key lesson is that generative modeling is not one technique. It is an ecosystem of probabilistic modeling strategies with different tradeoffs in likelihood, sample quality, inference, and training stability.
|
| 886 |
+
|
| 887 |
+
---
|
| 888 |
+
|
| 889 |
+
## 27. Representation learning
|
| 890 |
+
|
| 891 |
+
Representation learning is about learning  such that useful structure is preserved and nuisance variation is compressed.
|
| 892 |
+
|
| 893 |
+
This can be done through:
|
| 894 |
+
|
| 895 |
+
* supervised learning,
|
| 896 |
+
* self-supervised learning,
|
| 897 |
+
* generative modeling,
|
| 898 |
+
* multiview learning,
|
| 899 |
+
* bottleneck objectives.
|
| 900 |
+
|
| 901 |
+
A strong representation is not just a compressed vector; it is a structure-preserving abstraction that improves downstream learning and transfer.
|
| 902 |
+
|
| 903 |
+
---
|
| 904 |
+
|
| 905 |
+
## 28. Validation and rare-event thinking
|
| 906 |
+
|
| 907 |
+
Robust system evaluation requires more than aggregate accuracy.
|
| 908 |
+
|
| 909 |
+
For rare failure estimation, importance sampling plays a key role:
|
| 910 |
+
|
| 911 |
+
}{q(x_i)})
|
| 912 |
+
|
| 913 |
+
where  is the failure set.
|
| 914 |
+
|
| 915 |
+
The larger lesson is that trustworthy AI must account for:
|
| 916 |
+
|
| 917 |
+
* rare failures,
|
| 918 |
+
* adversarial behavior,
|
| 919 |
+
* reachability of unsafe states,
|
| 920 |
+
* runtime monitoring,
|
| 921 |
+
* property violation,
|
| 922 |
+
* explainability and post-deployment safety.
|
| 923 |
+
|
| 924 |
+
---
|
| 925 |
+
|
| 926 |
+
## 29. Fairness criteria
|
| 927 |
+
|
| 928 |
+
Three central statistical fairness notions are:
|
| 929 |
+
|
| 930 |
+
### Independence
|
| 931 |
+
|
| 932 |
+

|
| 933 |
+
|
| 934 |
+
### Separation
|
| 935 |
+
|
| 936 |
+

|
| 937 |
+
|
| 938 |
+
### Sufficiency
|
| 939 |
+
|
| 940 |
+

|
| 941 |
+
|
| 942 |
+
A major lesson from the fairness literature is that these criteria are generally **not simultaneously satisfiable** except under special conditions. That means fairness is not just a matter of choosing one formula; it requires thinking carefully about goals, institutions, social context, and the limits of observational criteria.
|
| 943 |
+
|
| 944 |
+
---
|
| 945 |
+
|
| 946 |
+
## 30. Causality
|
| 947 |
+
|
| 948 |
+
Causal reasoning asks not only what is associated, but what would happen under intervention.
|
| 949 |
+
|
| 950 |
+
The intervention notation is:
|
| 951 |
+
|
| 952 |
+
))
|
| 953 |
+
|
| 954 |
+
When backdoor adjustment is valid:
|
| 955 |
+
|
| 956 |
+
)=\sum_zp(y\mid%20x,z)p(z))
|
| 957 |
+
|
| 958 |
+
Causality matters because prediction alone cannot answer interventional questions, policy questions, or many scientific questions. This is one of the most important distinctions between pattern recognition and genuine decision-support intelligence.
|
| 959 |
+
|
| 960 |
+
---
|
| 961 |
+
|
| 962 |
+
That is why I recommend these books as a serious alternative to random course-hopping. Together they form a complete path from fundamentals to advanced AI understanding.
|
RL - An Introduction.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:db8fcf0fbb245d8c6779c02a2004e484c45b0f1c371ad04455a14ab0924c5166
|
| 3 |
+
size 4156279
|
The Elements of Statistical Learning.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:abc96e5915ef7dc313610b840f05581096e6e7750cd790d2883c4ce6c9719764
|
| 3 |
+
size 13301173
|
The Principles of Deep Learning Theory.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:39431828579ea31513eb6de8d6a4bee3d524d8a4f398537d5a0b3900dba92361
|
| 3 |
+
size 4786010
|
Understanding Deep Learning.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f8237d393163900fa8e43210e680a3f987b45ccac7750b372e156fae3df0bf32
|
| 3 |
+
size 22344992
|
book0 - A Probabilistic Perspective.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:bb6efb45beb4f29f018f3367fe3f350e4eef298b0b9ce0f4c8bba49e83d40e8b
|
| 3 |
+
size 26942669
|
book1 - Probabilistic Machine Learning - An Introduction.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:89749245bc8065d7575f990815c621a091de3facca1585168fc0369542742dcf
|
| 3 |
+
size 92323940
|
fairmlbook.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:da6e7782b714c52d2fb30d09bcf37db1e37a4fa94a3ba7ec7ca134ad82a60dc3
|
| 3 |
+
size 2220375
|
marl-book.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:50f0dc03b991d252b415dfd90ac393f1dcf855656dd93b0d4deb51ddfec704cc
|
| 3 |
+
size 8014508
|
mml-book.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3f87b70c64a35d30ec4e565b4d5cfd18fe913002d3b3bed44691c7d0838911bc
|
| 3 |
+
size 17565898
|
natural-language-processing-with-transformers.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6b93b285a59933120eabe4f097a14f2b67a722239bf5e06732fddac8cc20556f
|
| 3 |
+
size 18110498
|
understanding-machine-learning-theory-algorithms.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5ad0c69c922e47e423f6b469e8cfbaf07beae6933185af746b670911a8d163f2
|
| 3 |
+
size 2601512
|